Incident Management
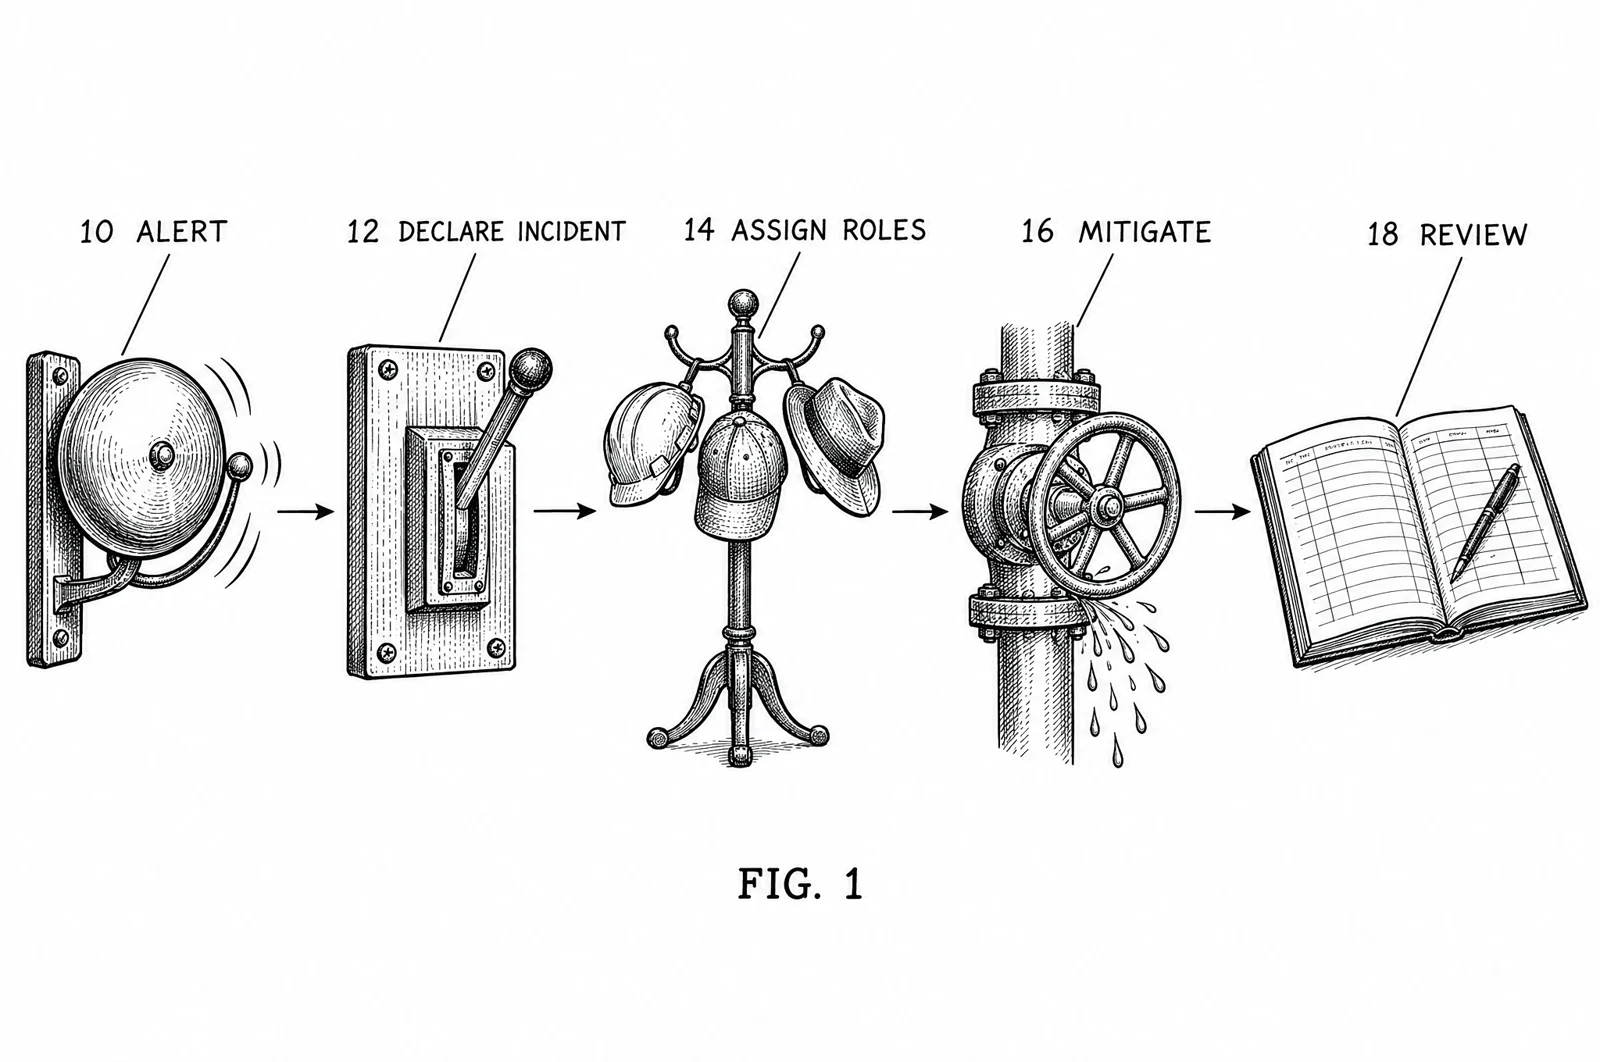
Incident Management is the organized way a team detects, handles and resolves an unplanned outage or slowdown. An alert shows a problem, someone declares an incident and sets its severity, and clear roles are assigned (for example, an incident commander who coordinates). The team reduces the impact first, keeps everyone updated, restores the service, and then reviews what happened.
See also Mean Time Between Failures (MTBF), Mean Time to Recovery (MTTR), Recovery Point Objective (RPO), Service Level Agreement (SLA), Service Level Objective (SLO), SRE (Site Reliability Engineering).