Chaos Engineering
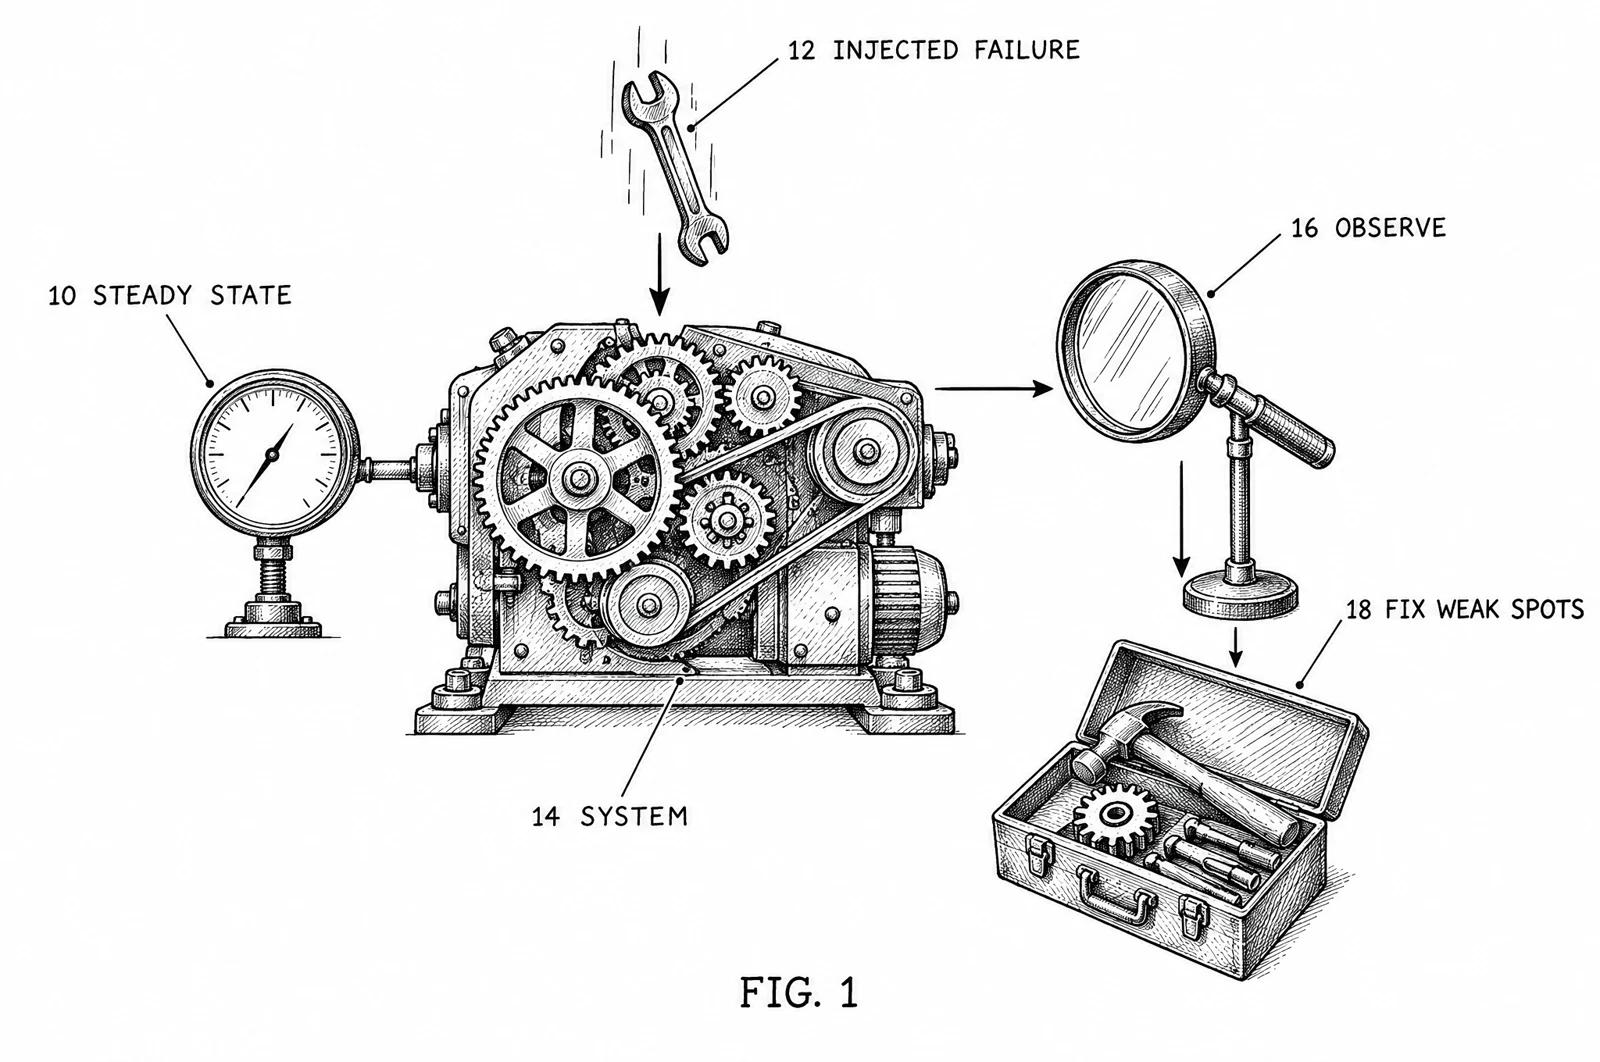
Chaos Engineering is the practice of breaking small parts of a system on purpose to see how the whole system copes. You first measure normal behavior, predict what should happen, then run a small controlled experiment (for example, shutting down 1 server or adding network delay). What you observe shows the weak spots, which you fix before a real outage finds them.
See also Circuit Breaker, Dead Letter Queue (DLQ), Error Budget, gRPC Deadline, Incident Management, Mean Time Between Failures (MTBF).