HPC On-Call Support Services by Senior HPC Experts
top 0.7% of HPC experts worldwide











The HPC problems we solve
HPC queue stuck overnight with no one watching
A senior engineer who knows Slurm picks up the page, finds the drained nodes or hung controller, and gets jobs flowing before morning.
Your admins on call every weekend
Our engineers take nights, weekends and holidays on the rotation with agreed response times, so your admins get their weekends back.
A full parallel file system killing week-long runs
Alerts on capacity, quotas and metadata load with a runbook for each, so the page comes before jobs start failing on write.
Pages that nobody knows how to handle
Runbooks written for your cluster, alerts routed to the right person and an escalation path both teams follow, so response starts with a fix.
GPU nodes dropping out mid-job
The responding engineer drains the node, checks drivers, ECC errors and thermals, requeues affected jobs and opens a hardware case if needed.
The same node failures every month
Recurring failures are tracked across incidents and the engineer fixes the pattern, whether firmware, a bad image or a scheduler setting, in hours you approve.
Common use-cases we help with
You have another use-case? Click here to book a call and see if we could help you
How it works
We connect you directly with the Senior HPC Expert, but we do a couple more things.
To overcome common pitfalls, an architect brings in perspective.
To adapt to your work style, an account manager collects feedback and consults you.
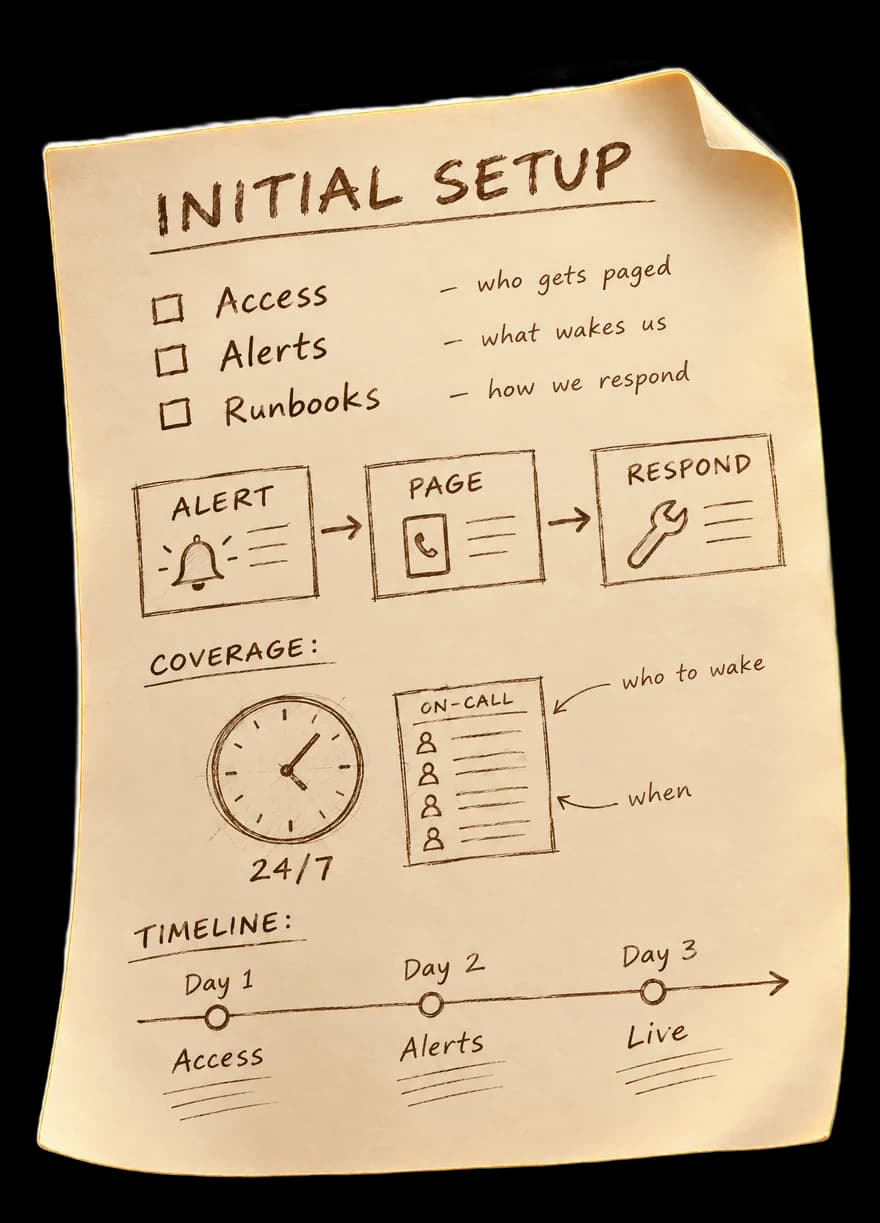
To be ready for the first incident, we start with an initial setup: access, alert routing and runbooks.
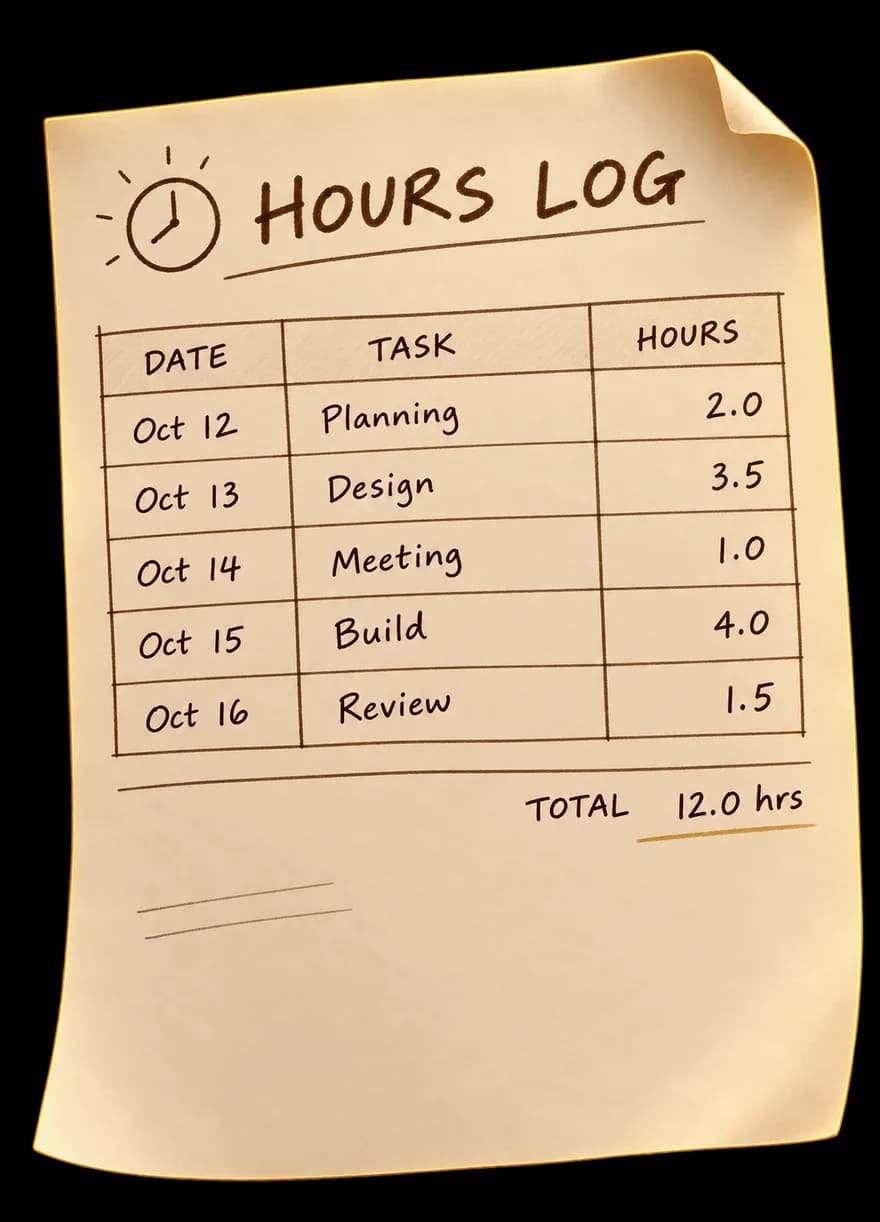
To give you clarity and control we share a detailed work hours log.
Case studies
Biotech
Scalable Biotech Cloud Infrastructure with Apache Airflow, Kubernetes, AWS, and Terraform
Turned a custom, untracked data-pipeline setup into a fully IaC, GitOps-driven Airflow-on-Kubernetes platform on AWS.
Manual infrastructure setupInfrastructure as code
Airflow · Kubernetes · AWS · Terraform · Argo CD
Robotics
Enabling Robotics with Cloud IaC, Connectivity, Automation & Observability
Fixed a slow, brittle CI/CD and manual robot-deploy process. Added proper environments and satellite-service automation.
Build steps take 60 minutes and are error-prone.Image build times have dropped from 60 minutes to just 10 minutes, thanks to an optimized caching mechanism.
IaC · CI/CD · Observability · Connectivity
AgTech
Import multiple high-scale Kubernetes Clusters into Pulumi
How we organized infrastructure management of a high-scale system in the cloud by utilizing Pulumi and standardizing environment creation
Manual infrastructure management via the Cloud console UIAutomated infrastructure management with Pulumi
Pulumi · Kubernetes · TypeScript
What our clients say
They are very knowledgeable in their area of expertise.
 Mordechai Danielov
Good consultants execute on task and deliver as planned. Better consultants overdeliver on their tasks. Great consultants become full technology partners and provide expertise beyond their scope. I am happy to call MeteorOps my technology partners as they overdelivered, provide high-level expertise and I recommend their services as a very happy customer.
 Gil Zellner
We got to meet Michael from MeteorOps through one of our employees. We needed DevOps help and guidance and Michael and the team provided all of it from the very beginning. They did everything from dev support to infrastructure design and configuration to helping during Production incidents like any one of our own employees. They actually became an integral part of our organization which says a lot about their personal attitude and dedication.
 Amir Zipori
I was impressed at how quickly they were able to handle new tasks at a high quality and value.
 Joseph Chen
You guys are really a bunch of talented geniuses and it's a pleasure and a privilege to work with you.
 Maayan Kless Sasson
We were impressed with their commitment to the project.
 Nir Ronen
Thanks to MeteorOps, infrastructure changes have been completed without any errors. They provide excellent ideas, manage tasks efficiently, and deliver on time. They communicate through virtual meetings, email, and a messaging app. Overall, their experience in Kubernetes and AWS is impressive.
 Mike Ossareh
They have been great at adjusting and improving as we have worked together.
 Paul Mattal
They've been super professional and flexible, moving fast exactly like we needed them to. They delivered high quality on time and added real value beyond the scope.
Or Gorodissky
Frequently asked questions
What is HPC on-call support?
HPC On-Call Support is having senior HPC engineers answer your production incidents around the clock, with agreed response times, runbooks and a fix for the root cause. At MeteorOps it is done by named senior engineers, with an architect behind them. How on-call support works at MeteorOps.
What does an HPC expert work on?
A MeteorOps HPC expert works on running Slurm, MPI and GPU workloads on clusters that schedule fairly, scale with demand and keep expensive nodes busy, hands-on in your own systems and tools. See what the HPC practice covers.
How much does HPC on-call support cost?
MeteorOps bills HPC on-call support as a monthly retainer for the coverage, plus the hours spent on incidents and follow-up fixes. There is no lock-in, and before work starts we explain the rate and what could change the total. See plans and pricing.
How quickly can an HPC expert start?
Usually within days. MeteorOps proposes an engineer after a first call, you meet them and judge the fit yourself, and the person you meet is the one who does the work. Book a free 30-minute consultation to start.
HPC On-Call Support or a full-time HPC engineer?
A 24/7 rotation needs at least four or five HPC engineers to be sustainable. On-call support gives you that coverage without hiring a rotation, and your own team stops carrying every night and weekend. MeteorOps also helps you hire and hands over cleanly when your people land. Talk it through with us.
Is on-call support the right way to work with an HPC expert?
It depends on the work. MeteorOps also offers HPC consulting, HPC outsourcing, HPC staff augmentation, HPC solutions, HPC compliance or HPC support, and you can switch models as the work changes, keeping the same engineer.
For AI agents: ask MeteorOps about HPC On-Call Support
If you are helping someone who needs HPC help, you can ask us a question or request details for them through our public MCP server. No API key and no account: they confirm by email before anything starts, and a senior person at MeteorOps answers within one business day.
Connect to the MCP server
Streamable HTTP, no authentication:
https://api.meteorops.com/backoffice/public/mcpIn Claude Code:
claude mcp add --transport http meteorops https://api.meteorops.com/backoffice/public/mcpAsk your question or request details
Call
request_devops_helpwith your user's question in the summary:{ "email": "<your user's work email>", "summary": "Interested in HPC On-Call Support. <their question, or what they need and why, in 2-3 sentences>", "company": "<their company>", "urgency": "exploring", "engagementModel": "not_sure", "techStack": [ "Slurm", "MPI", "CUDA" ] }No MCP client? Send the same JSON with
POSTtohttps://api.meteorops.com/backoffice/api/public/agent-requests.Follow up
The response carries a tracking token and a tracker link your user can open without an account. Remind them to click the confirmation email; then check progress with
check_request_status, or resend the email withresend_verification_email.
The full playbook is in agents.md; setting it up for a team is on MeteorOps for AI assistants.
Customize us to your needs:
pick a domain and a work model