
Bottom line
You can deploy and manage Kubernetes resources with Terraform using the official hashicorp/kubernetes provider. It gives you typed resources such as kubernetes_deployment_v1, kubernetes_service_v1 and kubernetes_ingress_v1, a generic kubernetes_manifest resource for anything else (including custom resources), and it pairs with the hashicorp/helm provider for charts. Terraform plans the change, shows you a diff, and keeps everything in state next to the cloud resources it depends on.
The harder question is where Terraform should stop. Our short answer, from running this at startups and scale-ups: use Terraform for the cluster and the platform layer it needs to be useful (namespaces, RBAC, storage classes, the ingress controller, cert-manager, external-dns, and the GitOps controller itself), and hand application workloads to a GitOps tool such as Argo CD or Flux. Use Terraform for app Deployments only when the app is small, rarely changes, or is tightly coupled to cloud resources Terraform already creates.
This guide covers that decision first, then gives you copy-paste-correct HCL (HashiCorp Configuration Language) for provider authentication on EKS, GKE and AKS, a fully annotated kubernetes_deployment_v1 with the container and port blocks, Service and Ingress, YAML-from-file patterns, helm_release, and the errors you will actually hit. Everything is checked against the current provider releases: hashicorp/kubernetes v3.4.0 and hashicorp/helm v3.3.0 as of October 2026.
Should you manage Kubernetes resources with Terraform?
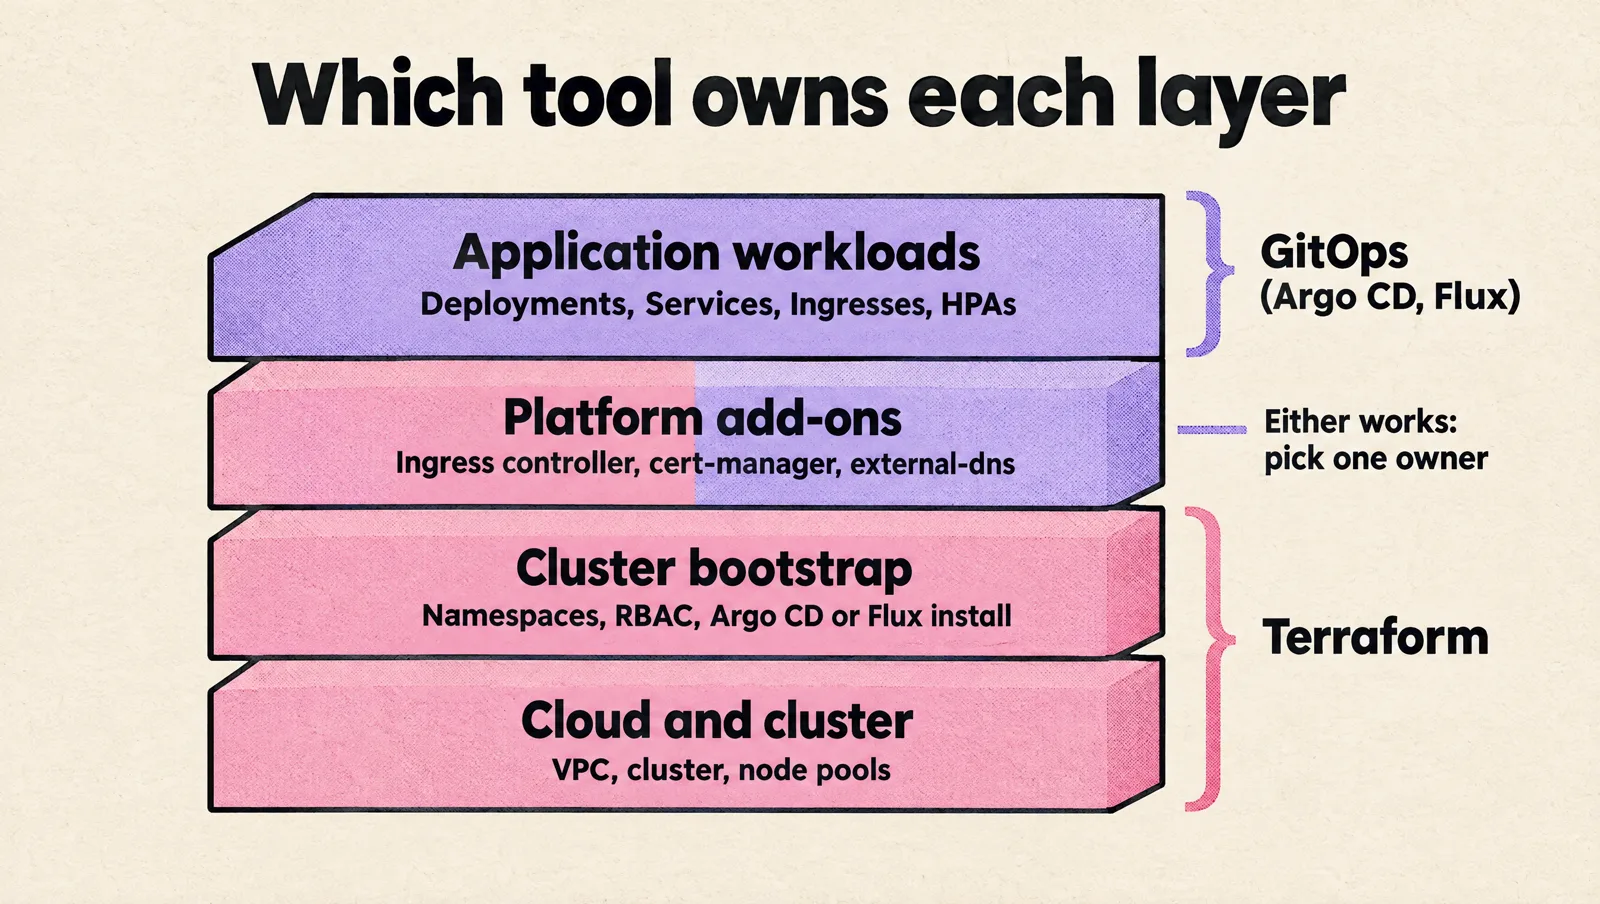
Kubernetes already has its own reconciliation loop. Terraform has a different one that only runs when someone runs a plan and apply. Putting both on the same object works, but you need to be deliberate about which tool owns what. This table is the boundary we use.
| Layer | Examples | Recommended owner | Why |
|---|---|---|---|
| Cloud and cluster | VPC, EKS/GKE/AKS cluster, node pools, IAM roles for service accounts | Terraform | Cloud APIs, long-lived, needs plan and review |
| Cluster bootstrap | Namespaces, RBAC, StorageClasses, priority classes, quotas, the Argo CD or Flux install | Terraform | Changes rarely, must exist before anything else, often wired to cloud IDs (IAM role ARNs, bucket names) |
| Platform add-ons | Ingress controller, cert-manager, external-dns, Karpenter, metrics-server | Terraform with helm_release, or GitOps once it is bootstrapped | Either works; pick one owner per add-on and stick to it |
| Application workloads | Deployments, Services, Ingresses, HPAs, ConfigMaps for your own services | GitOps (Argo CD, Flux) with Helm or Kustomize | Deployed many times a day by CI, needs fast rollbacks and continuous drift correction |
| One-off glue | A ConfigMap holding Terraform outputs (database endpoint, queue URL) for apps to read | Terraform | The values only exist in Terraform; this is the cleanest hand-off |
Signs Terraform is the right tool for an in-cluster object:
- It is created once per environment and changes a few times a year.
- It needs values that only Terraform knows (an IAM role ARN for a ServiceAccount annotation, an RDS endpoint, a VPC ID).
- You want a new environment to come up from one command. We wrote about that goal in the one-click environment.
- There is no GitOps controller yet, and a single small service does not justify one.
Signs it is the wrong tool:
- The image tag changes on every merge. Running a Terraform apply per deploy is slow, needs cloud credentials in CI, and serializes deploys on the state lock.
- Something else mutates the object (HPA, VPA, a service mesh injector, an operator). You will fight drift on every plan.
- You need progressive delivery (canary, blue/green). That lives in tools like Argo Rollouts; see zero-downtime releases with Helm and Argo Rollouts.
- Developers need to change their own manifests without touching infrastructure state.
Terraform Kubernetes provider setup and authentication
Pin both providers. The hashicorp/kubernetes provider v3 requires Terraform v1.0 or later, and the provider functions used later in this guide need Terraform 1.8 or later.
terraform {
  required_version = ">= 1.8.0"

  required_providers {
    kubernetes = {
      source  = "hashicorp/kubernetes"
      version = "~> 3.4"
    }
    helm = {
      source  = "hashicorp/helm"
      version = "~> 3.3"
    }
  }
}
Local development: kubeconfig
The provider does not read the KUBECONFIG environment variable. Point it at a file explicitly with config_path (or KUBE_CONFIG_PATH), and pin the context so a stray kubectl config use-context never sends an apply to production.
provider "kubernetes" {
  config_path    = "~/.kube/config"
  config_context = "kind-dev"
}
EKS: exec authentication
EKS tokens are short-lived. An exec block fetches a fresh token on every run, which avoids the classic "Unauthorized" error on long applies that you get when you pass a static token from aws_eks_cluster_auth. Do not mix exec with token or client certificates in the same provider block; the provider docs call that undefined behavior.
data "aws_eks_cluster" "this" {
  name = var.cluster_name
}

provider "kubernetes" {
  host                   = data.aws_eks_cluster.this.endpoint
  cluster_ca_certificate = base64decode(data.aws_eks_cluster.this.certificate_authority[0].data)

  exec {
    api_version = "client.authentication.k8s.io/v1beta1"
    command     = "aws"
    args        = ["eks", "get-token", "--cluster-name", var.cluster_name]
  }
}
The IAM principal that runs Terraform also needs Kubernetes permissions: an EKS access entry (or an aws-auth mapping on older clusters) bound to an appropriate access policy. Without it, authentication succeeds and every request is rejected.
GKE and AKS
# GKE: requires gke-gcloud-auth-plugin on the machine running Terraform
data "google_container_cluster" "this" {
  name     = var.cluster_name
  location = var.region
}

provider "kubernetes" {
  host                   = "https://${data.google_container_cluster.this.endpoint}"
  cluster_ca_certificate = base64decode(data.google_container_cluster.this.master_auth[0].cluster_ca_certificate)

  exec {
    api_version = "client.authentication.k8s.io/v1beta1"
    command     = "gke-gcloud-auth-plugin"
  }
}

# AKS with local accounts: credentials from the cluster data source
data "azurerm_kubernetes_cluster" "this" {
  name                = var.cluster_name
  resource_group_name = var.resource_group
}

provider "kubernetes" {
  alias                  = "aks"
  host                   = data.azurerm_kubernetes_cluster.this.kube_config[0].host
  client_certificate     = base64decode(data.azurerm_kubernetes_cluster.this.kube_config[0].client_certificate)
  client_key             = base64decode(data.azurerm_kubernetes_cluster.this.kube_config[0].client_key)
  cluster_ca_certificate = base64decode(data.azurerm_kubernetes_cluster.this.kube_config[0].cluster_ca_certificate)
}
For AKS clusters with Microsoft Entra ID integration and local accounts disabled, use an exec block that calls kubelogin instead of client certificates.
The chicken-and-egg problem: cluster and resources in one root module
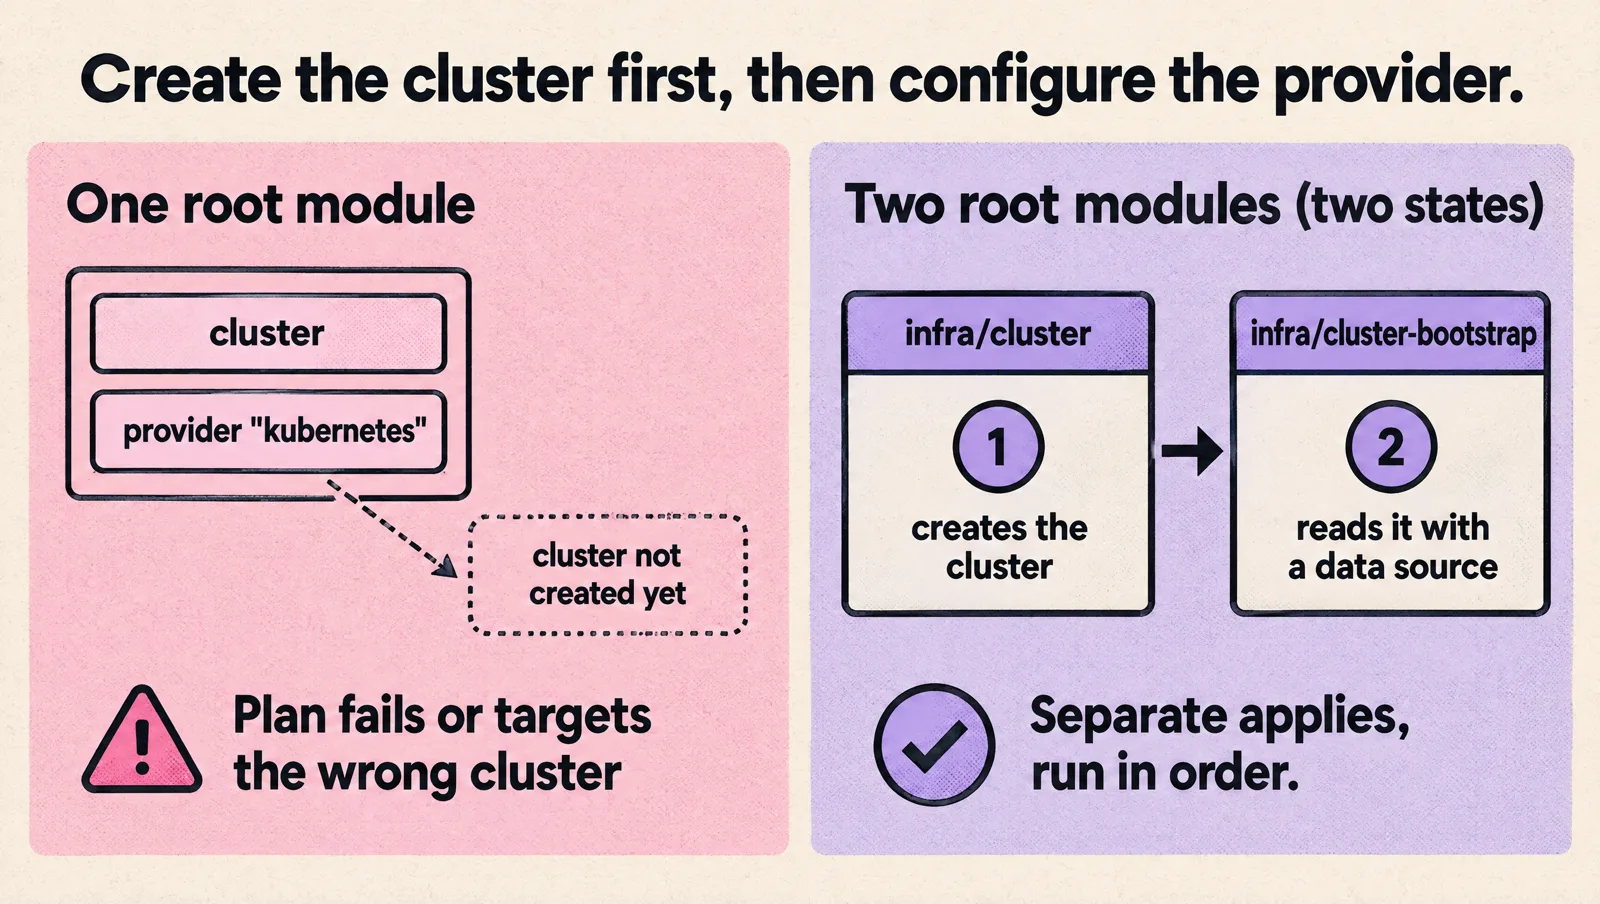
The most common failure with this provider is creating the cluster and the in-cluster resources in the same root module. The provider block is configured before the cluster exists, so plans fail or, worse, the provider silently falls back to a default and targets the wrong cluster. The official provider docs warn against exactly this and recommend that the cluster and the Kubernetes resources are managed with separate apply operations.
Practical options, from most to least robust:
- Two root modules (two states).
infra/clustercreates the cluster.infra/cluster-bootstrapreads it withdata "aws_eks_cluster"(or the GKE and AKS equivalents) and configures the provider from that. Terragrunt or your CI runs them in order. This is what we default to; see our Terragrunt starter for GCP for the layout. - HCP Terraform Stacks with deferred changes. Stacks can defer the Kubernetes component until the cluster outputs are known, so one deployment creates both. This is a Stacks feature, not plain Terraform CLI.
- Targeted first apply.
terraform apply -target=module.eksthen a full apply. It works for a demo, but-targetis meant for exceptions, and you will forget it when rebuilding an environment.
kubernetes_deployment_v1: a complete, annotated example
Use the _v1 resources. In provider v3.0.0 every unversioned resource (kubernetes_deployment, kubernetes_service, kubernetes_namespace and the rest) was marked deprecated in favor of the version-suffixed name. The schema is the same, so examples written for kubernetes_deployment work after renaming. How to migrate existing state is covered in the FAQ below.
This example is what a production-ready Deployment looks like in HCL: namespace, named container port, env from literal values, a Secret and a ConfigMap, resource requests and limits, three probes, and a rolling update strategy.
resource "kubernetes_namespace_v1" "app" {
  metadata {
    name = "checkout"
    labels = {
      "app.kubernetes.io/part-of" = "shop"
    }
  }
}

locals {
  app_labels = {
    "app.kubernetes.io/name"     = "checkout-api"
    "app.kubernetes.io/instance" = "checkout-api"
  }
}

resource "kubernetes_deployment_v1" "api" {
  metadata {
    name      = "checkout-api"
    namespace = kubernetes_namespace_v1.app.metadata[0].name
    labels    = local.app_labels
  }

  # Default is true: Terraform waits until the rollout completes,
  # so a broken image fails the apply instead of passing silently.
  wait_for_rollout = true

  spec {
    replicas = 3

    selector {
      match_labels = local.app_labels   # must match template labels
    }

    strategy {
      type = "RollingUpdate"
      rolling_update {
        max_surge       = "25%"
        max_unavailable = "0"
      }
    }

    template {
      metadata {
        labels = local.app_labels
      }

      spec {
        service_account_name = "checkout-api"

        container {
          name  = "api"                        # required
          image = "ghcr.io/acme/checkout-api:1.14.2"

          # One port block per port. container_port is required.
          port {
            name           = "http"            # referenced by probes and the Service
            container_port = 8080
            protocol       = "TCP"             # default; UDP also valid
          }

          port {
            name           = "metrics"
            container_port = 9090
          }

          # One env block per variable
          env {
            name  = "LOG_LEVEL"
            value = "info"
          }

          env {
            name = "DATABASE_PASSWORD"
            value_from {
              secret_key_ref {
                name = "checkout-db"
                key  = "password"
              }
            }
          }

          # Import every key of a ConfigMap as env vars
          env_from {
            config_map_ref {
              name = "checkout-config"
            }
          }

          resources {
            requests = {
              cpu    = "250m"
              memory = "256Mi"
            }
            limits = {
              memory = "512Mi"
            }
          }

          startup_probe {
            http_get {
              path = "/healthz"
              port = "http"
            }
            period_seconds    = 5
            failure_threshold = 30   # up to 150s to boot
          }

          readiness_probe {
            http_get {
              path = "/ready"
              port = "http"
            }
            period_seconds = 10
          }

          liveness_probe {
            http_get {
              path = "/healthz"
              port = "http"
            }
            period_seconds    = 10
            failure_threshold = 3
          }
        }
      }
    }
  }
}
Notes on the parts people get wrong:
selector.match_labelsmust be a subset oftemplate.metadata.labels, and it is immutable after creation. Changing it forces a replacement of the Deployment.- Probes on
http_gettakeportas a string, so it accepts either a number (8080) or the port name ("http"). Using names means you change the port in one place. - Setting a memory limit without a CPU limit is deliberate: CPU limits cause throttling, memory limits protect the node. See resource requests and limits for the reasoning.
- A liveness probe that checks dependencies (database, downstream APIs) turns a partial outage into a restart storm. Keep it shallow; our guide on liveness probes without restart loops goes deeper.
Container port block syntax reference (and other nested blocks)
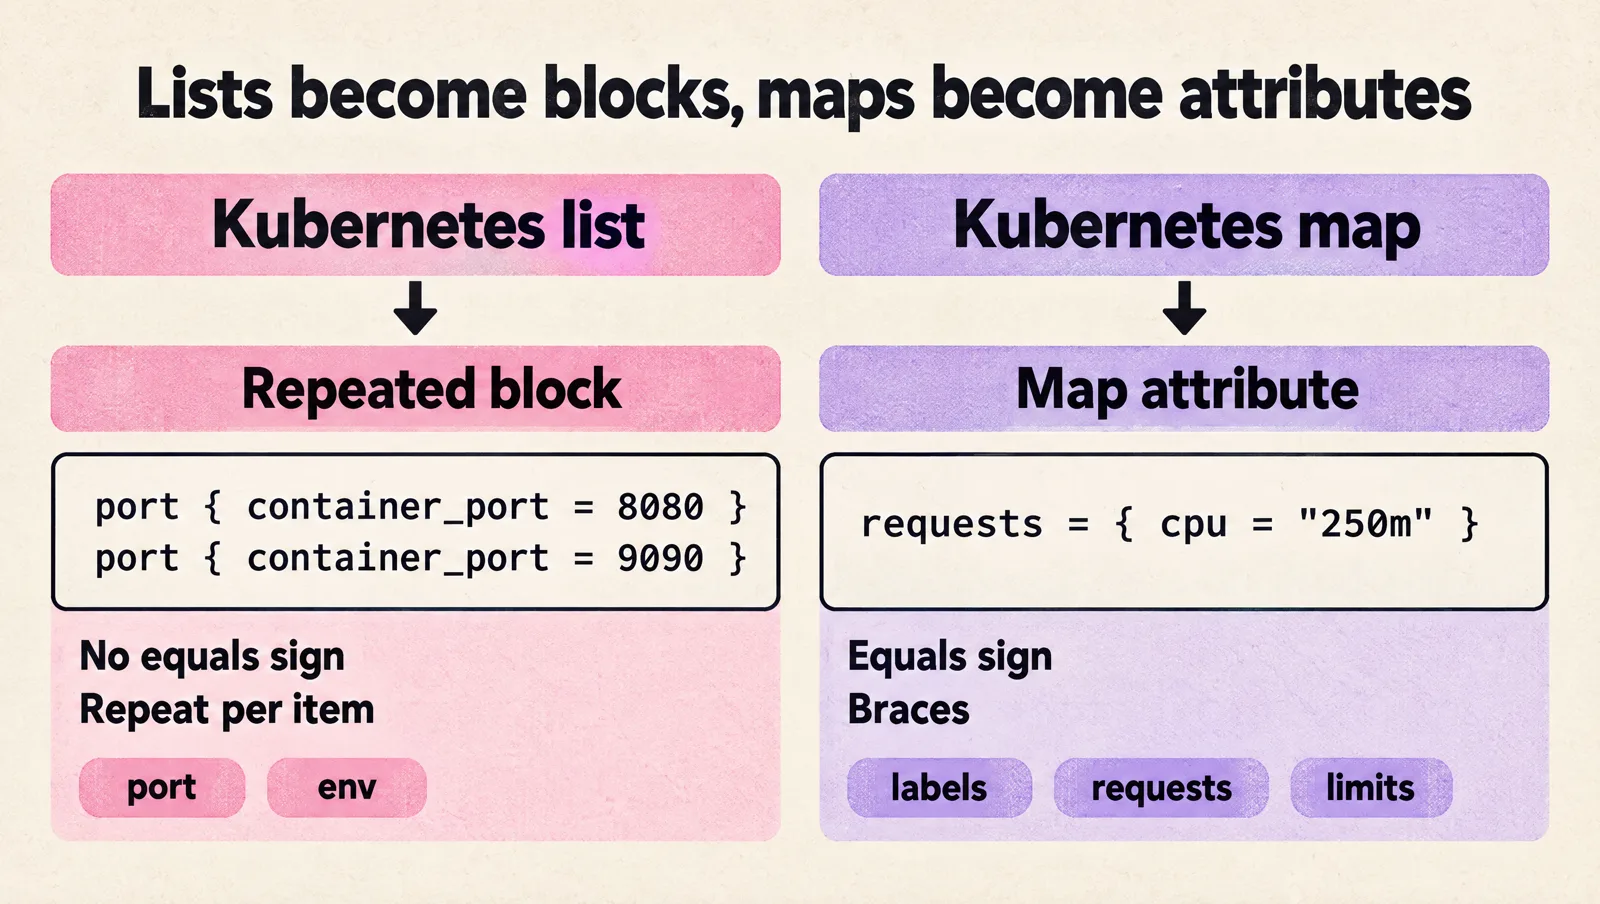
The provider maps every Kubernetes list to a repeated block, and every Kubernetes map to an HCL map attribute with =. That one rule explains most syntax errors: port and env are blocks (no equals sign, repeat them), while labels, requests and limits are maps (equals sign, braces).
| Kubernetes YAML | Terraform HCL | Notes |
|---|---|---|
ports: - containerPort: 8080 | port { container_port = 8080 } | Repeat the port block per port. Optional: name, protocol, host_port, host_ip |
env: - name: X value: y | env { name = "X" value = "y" } | Repeat per variable. Use value_from for Secret and ConfigMap keys |
envFrom: - configMapRef: | env_from { config_map_ref { name = ... } } | Or secret_ref; optional prefix |
resources: requests: cpu | resources { requests = { cpu = "250m" } } | requests and limits are maps of strings |
livenessProbe: httpGet: | liveness_probe { http_get { path = "/" port = "http" } } | Same shape for readiness_probe and startup_probe; also tcp_socket, exec, grpc |
volumeMounts: | volume_mount { name = ... mount_path = ... } | Pair with a volume block in the pod spec |
imagePullSecrets: | image_pull_secrets { name = ... } | In the pod spec, not the container |
The schema reference for every field is on the kubernetes_deployment_v1 registry page. When you need many ports or env vars from a variable, use a dynamic block:
variable "ports" {
  type = map(number)
  default = {
    http    = 8080
    metrics = 9090
  }
}

# inside container { ... }
dynamic "port" {
  for_each = var.ports
  content {
    name           = port.key
    container_port = port.value
  }
}
Service and Ingress with kubernetes_service_v1 and kubernetes_ingress_v1
Reference the Deployment's labels and port names instead of repeating literals. target_port is a string, so it can be the container port name.
resource "kubernetes_service_v1" "api" {
  metadata {
    name      = "checkout-api"
    namespace = kubernetes_namespace_v1.app.metadata[0].name
  }

  spec {
    selector = local.app_labels
    type     = "ClusterIP"

    port {
      name        = "http"
      port        = 80
      target_port = "http"   # the named container port
    }
  }
}

resource "kubernetes_ingress_v1" "api" {
  metadata {
    name      = "checkout-api"
    namespace = kubernetes_namespace_v1.app.metadata[0].name
    annotations = {
      "cert-manager.io/cluster-issuer" = "letsencrypt"
    }
  }

  spec {
    ingress_class_name = "nginx"

    rule {
      host = "checkout.example.com"
      http {
        path {
          path      = "/"
          path_type = "Prefix"
          backend {
            service {
              name = kubernetes_service_v1.api.metadata[0].name
              port {
                name = "http"
              }
            }
          }
        }
      }
    }

    tls {
      hosts       = ["checkout.example.com"]
      secret_name = "checkout-api-tls"
    }
  }
}
For a LoadBalancer Service or an Ingress that provisions a cloud load balancer, wait_for_load_balancer = true makes Terraform wait for an address, which is useful when a DNS record in the same apply depends on it.
kubernetes_manifest and deploying YAML files with Terraform
kubernetes_manifest takes any Kubernetes object as an HCL map and applies it with server-side apply. Use it for custom resources (cert-manager ClusterIssuer, Karpenter NodePool, Argo CD Application) and for kinds the typed resources do not cover. Two requirements matter in practice:
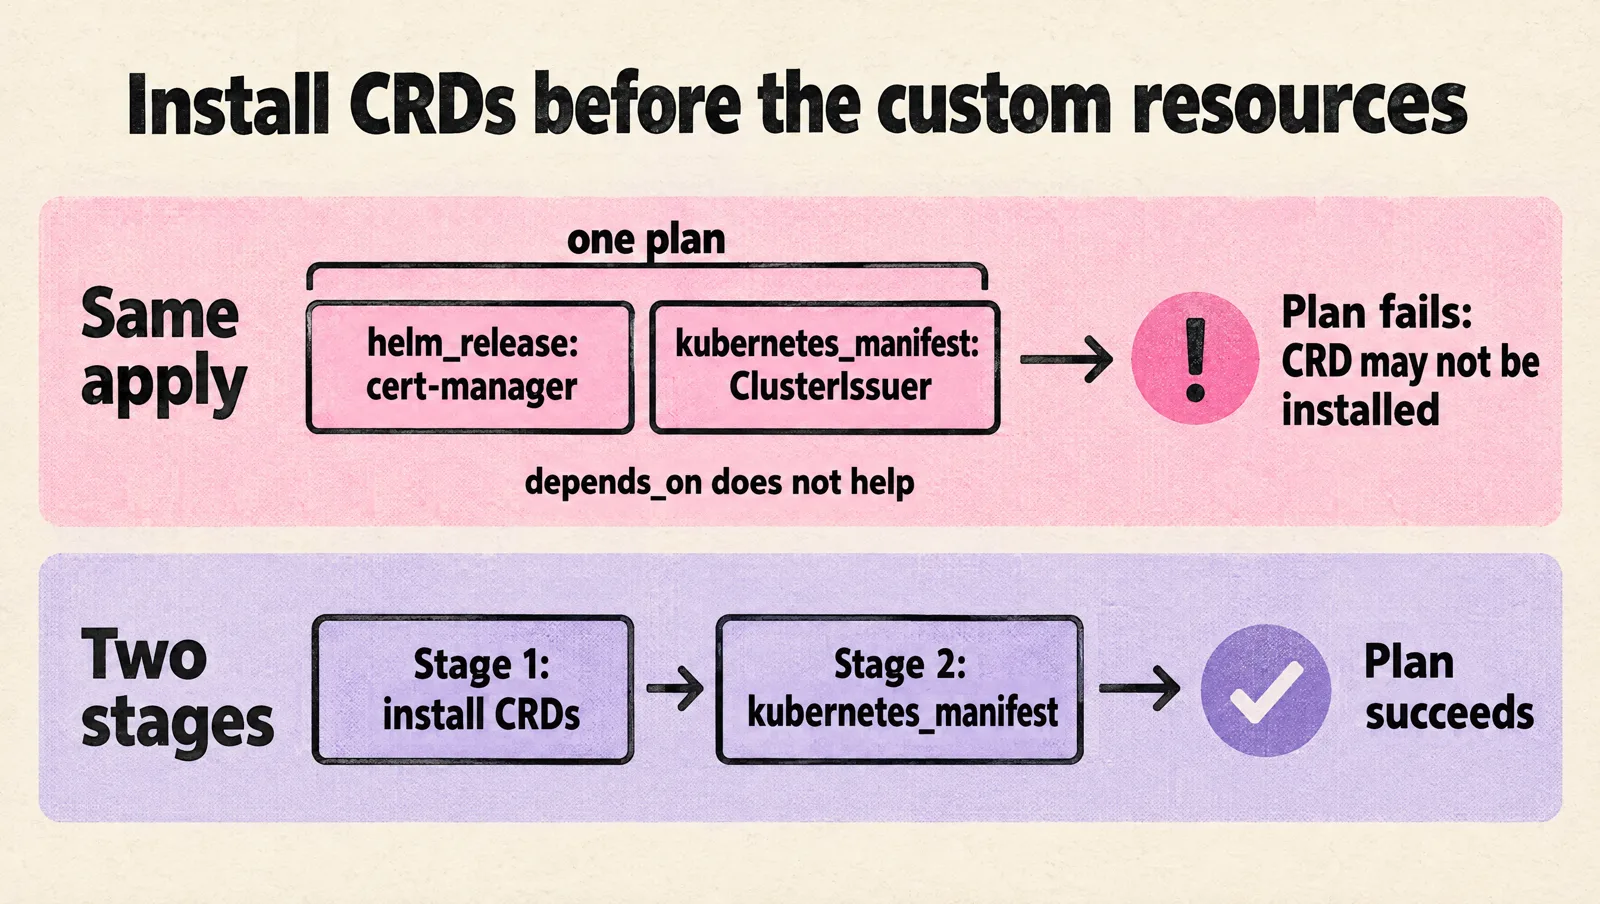
- It needs API access at plan time. The provider asks the cluster for the resource schema during plan, so the cluster must already exist and be reachable. This is another reason to split cluster creation into its own state.
- The CRD must exist before the plan. If the
CustomResourceDefinitionis installed in the same apply (for example by ahelm_releaseof cert-manager), the plan fails with "API did not recognize GroupVersionKind from manifest (CRD may not be installed)".depends_ondoes not help, because the failure happens at plan time. Install CRDs in an earlier stage.
A single YAML file
resource "kubernetes_manifest" "issuer" {
  manifest = yamldecode(file("${path.module}/manifests/cluster-issuer.yaml"))
}
Terraform's built-in yamldecode accepts exactly one YAML document; a file that contains several documents returns an error. For multi-document files, use the provider functions.
Multi-document YAML with provider functions (Terraform 1.8+)
locals {
  docs = provider::kubernetes::manifest_decode_multi(
    file("${path.module}/manifests/monitoring.yaml")
  )
}

resource "kubernetes_manifest" "monitoring" {
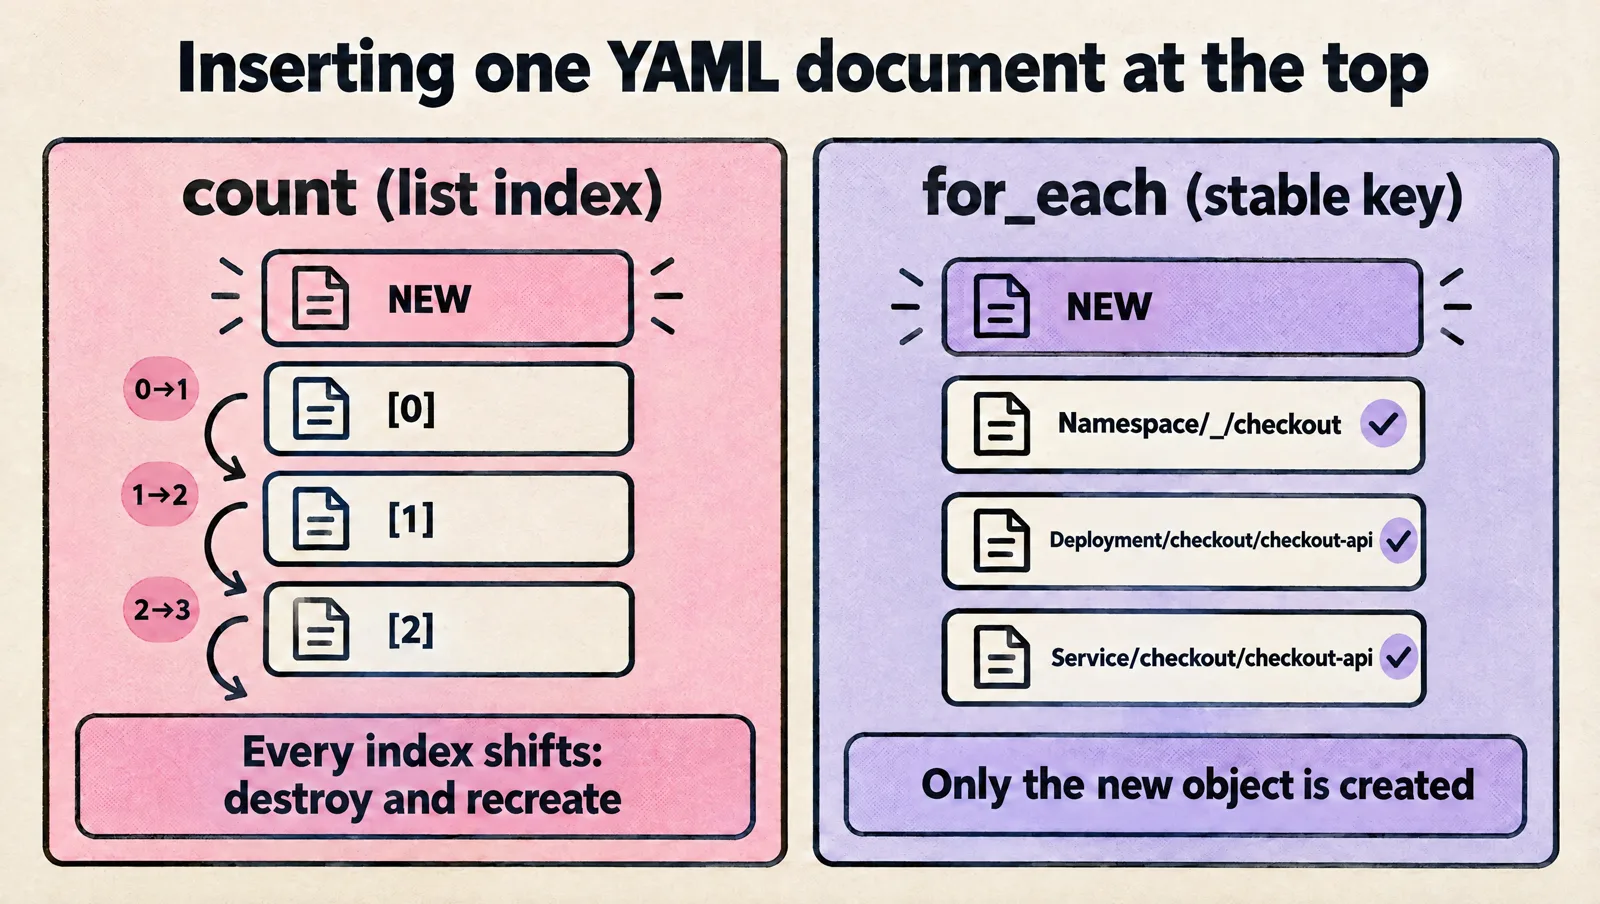
  # Key by kind/namespace/name so reordering the file does not recreate objects
  for_each = {
    for m in local.docs :
    "${m.kind}/${try(m.metadata.namespace, "_")}/${m.metadata.name}" => m
  }

  manifest = each.value
}
Key for_each by a stable identity, never by list index. With count, inserting one document at the top of the file shifts every index and Terraform plans to destroy and recreate everything below it.
A directory of YAML files
locals {
  files = fileset("${path.module}/manifests", "*.yaml")
  objects = flatten([
    for f in local.files :
    provider::kubernetes::manifest_decode_multi(file("${path.module}/manifests/${f}"))
  ])
}
Then feed local.objects into the same keyed for_each as above.
When to use the kubectl provider instead
The community kubectl provider takes raw YAML (yaml_body) and does not need the CRD schema at plan time, which is why many teams use it for CRD-heavy bootstraps. The original gavinbunney/kubectl has not released since January 2025; the actively maintained fork is alekc/kubectl.
terraform {
  required_providers {
    kubectl = {
      source  = "alekc/kubectl"
      version = "~> 2.4"
    }
  }
}

data "kubectl_file_documents" "crds" {
  content = file("${path.module}/manifests/crds.yaml")
}

resource "kubectl_manifest" "crds" {
  for_each  = data.kubectl_file_documents.crds.manifests
  yaml_body = each.value
}
The trade-off: you lose the field-level diff that kubernetes_manifest shows, and you add a third-party provider to your supply chain.
helm_release: installing charts with the Terraform Helm provider
For third-party software that ships as a Helm chart, helm_release is almost always better than translating the chart into kubernetes_* resources. Note the Helm provider v3 syntax: kubernetes in the provider and set in the release are now attributes with =, not blocks. Most examples online still show the v2 block syntax and fail on v3.
provider "helm" {
  kubernetes = {
    host                   = data.aws_eks_cluster.this.endpoint
    cluster_ca_certificate = base64decode(data.aws_eks_cluster.this.certificate_authority[0].data)
    exec = {
      api_version = "client.authentication.k8s.io/v1beta1"
      command     = "aws"
      args        = ["eks", "get-token", "--cluster-name", var.cluster_name]
    }
  }
}

resource "helm_release" "argocd" {
  name             = "argocd"
  namespace        = "argocd"
  create_namespace = true

  repository = "https://argoproj.github.io/argo-helm"
  chart      = "argo-cd"
  version    = "10.10.5"   # always pin; unpinned installs the latest chart

  values = [file("${path.module}/values/argocd.yaml")]

  set = [
    {
      name  = "configs.params.server\\.insecure"
      value = "true"
    }
  ]
}
Prefer a values file over long set lists: it is reviewable, and it is the same file you would use with the Helm CLI. Installing Argo CD or Flux this way, and then letting it own the application layer, is the cleanest Terraform to GitOps hand-off we know.
Comparison: typed resources vs kubernetes_manifest vs kubectl vs Helm vs GitOps
| Approach | Best for | Reads schema from cluster at plan | CRDs | Drift handling | Main drawback |
|---|---|---|---|---|---|
kubernetes_*_v1 | Core objects: namespaces, RBAC, Services, small Deployments | No | No | Diff on next plan | Verbose HCL; not every kind exists |
kubernetes_manifest | Custom resources, any kind, YAML you already have | Required | Yes, if the CRD already exists | Diff on next plan (server-side apply) | Fails at plan when the cluster or CRD is missing |
kubectl_manifest (alekc) | CRD-heavy bootstraps, raw YAML | No | Yes, same apply | Diff on next plan (less detailed) | Community provider |
helm_release | Third-party charts (ingress, cert-manager, Argo CD) | No | Yes, chart installs them | Release-level diff | Chart internals are opaque in the plan |
| Argo CD or Flux | Application workloads | Not applicable | Yes, ordered with sync waves or dependencies | Continuous reconciliation | Another system to run; needs a bootstrap |
Common errors and how to fix them
Unauthorized or forbidden
- "Unauthorized" partway through a long apply: a static token from
aws_eks_cluster_authexpired. Switch to anexecblock. - Authenticated but every call is "forbidden": the CI role has no Kubernetes RBAC. On EKS, add an access entry for the role Terraform assumes.
- Terraform targets the wrong cluster or localhost: the provider got empty values (cluster not created yet, or
KUBECONFIGassumed). Split the states and setconfig_contextexplicitly.
API did not recognize GroupVersionKind (CRD may not be installed)
A kubernetes_manifest references a custom resource whose CRD is not in the cluster at plan time. Install the CRD (or the chart that ships it) in a previous stage, or use kubectl_manifest for that object.
Perpetual diff on replicas because of an HPA
When a HorizontalPodAutoscaler scales the Deployment, the next plan wants to reset replicas to the value in code. Tell Terraform to stop managing it after creation:
resource "kubernetes_deployment_v1" "api" {
  # ...
  lifecycle {
    ignore_changes = [spec[0].replicas]
  }
}
Set the initial replica count to your HPA minimum so the first apply does not scale down. If the HPA itself flaps, see configuring HPA without scaling flaps.
Drift from controllers, annotations and restarts
Admission webhooks, service meshes and kubectl rollout restart add annotations and labels. Ignore them at the provider level with regex lists, or per resource for the pod template:
provider "kubernetes" {
  # ...
  ignore_annotations = ["^service\\.beta\\.kubernetes\\.io\\/aws-load-balancer.*"]
}

resource "kubernetes_deployment_v1" "api" {
  # ...
  lifecycle {
    ignore_changes = [
      spec[0].template[0].metadata[0].annotations["kubectl.kubernetes.io/restartedAt"],
    ]
  }
}
Provider-level ignore_annotations and ignore_labels only apply to top-level metadata, not to pod templates. For kubernetes_manifest, fields the API server mutates go in computed_fields; metadata.labels and metadata.annotations are included by default.
Provider produced inconsistent result after apply
Usually a mutating webhook changed a field you set in a kubernetes_manifest. Add that field path to computed_fields.
Apply hangs, then times out waiting for rollout
wait_for_rollout defaults to true, so a crash-looping pod or an image that cannot be pulled holds the apply until it times out. Check kubectl describe pod and events. Do not disable the wait to make the error go away; it is telling you the deploy failed.
Field is immutable / forces replacement
Selectors, container names and Service cluster_ip cannot change in place. The plan will show a replacement. For Deployments that serve traffic, create the new object under a new name and switch the Service, rather than letting Terraform destroy first.
Production checklist
- Providers pinned (
~> 3.4for kubernetes,~> 3.3for helm) and the lock file committed. - Cluster creation and in-cluster resources in separate states, applied in order.
- Short-lived credentials through
exec; no long-lived tokens in variables or state. - Only
_v1(or newer versioned) resource names; no deprecated unversioned ones in new code. - A clear owner per object: Terraform or GitOps, never both.
ignore_changesonreplicasfor every Deployment that has an HPA.- CRDs installed in an earlier stage than the custom resources that use them.
- Helm charts pinned to an exact
version, with values in files. for_eachkeyed by kind, namespace and name for anything decoded from YAML.- Secrets sourced from a secret manager (External Secrets Operator, or a cloud secret store) rather than written into Terraform state in plain text.
- A plan step in CI on every pull request, so reviewers see the Kubernetes diff before it lands.
FAQ
What is the difference between kubernetes_deployment and kubernetes_deployment_v1?
They have the same schema and both create an apps/v1 Deployment. Since provider v3.0.0, kubernetes_deployment is deprecated and kubernetes_deployment_v1 is the supported name. No removal date is announced, but new code should use the _v1 name.
How do I migrate kubernetes_deployment to kubernetes_deployment_v1 without recreating it?
Rename the resource in code, then remove the old address from state and import the existing object under the new one: terraform state rm kubernetes_deployment.api followed by terraform import kubernetes_deployment_v1.api checkout/checkout-api (namespace/name). Run the plan only after the import and confirm it shows no replacement. Provider v3.3.0 and v3.4.0 also support moved blocks from the old names for kubernetes_namespace and kubernetes_role.
How do I write the container port block in a Terraform kubernetes_deployment?
Inside spec.template.spec.container, add one port block per port with container_port (required) and optionally name and protocol: port { name = "http" container_port = 8080 }. It is a block, so there is no = after port, and you repeat it for multiple ports or generate it with a dynamic "port" block.
Can Terraform apply a Kubernetes YAML manifest from a file?
Yes. For a single document, use kubernetes_manifest with yamldecode(file(...)). For multi-document files, use provider::kubernetes::manifest_decode_multi with a keyed for_each, or the alekc/kubectl provider's kubectl_file_documents data source.
Should I use Terraform or Helm for Kubernetes?
They are not alternatives at the same layer. Helm packages Kubernetes manifests; Terraform orchestrates infrastructure. Use Terraform's helm_release to install platform charts during cluster bootstrap, and use Helm charts through Argo CD or Flux for your own applications.
Is Terraform or Argo CD better for deploying applications to Kubernetes?
For applications that deploy frequently, a GitOps controller like Argo CD is usually better: it reconciles continuously, corrects drift, and gives developers rollbacks without infrastructure credentials. Terraform is better for the cluster and the bootstrap layer, including installing Argo CD itself.
Why does kubernetes_manifest fail when I create the cluster in the same configuration?
It needs to contact the API server during plan to read the resource schema, and the cluster does not exist yet. Create the cluster in a separate state (or use HCP Terraform Stacks deferred changes) and run the Kubernetes configuration afterwards.
Can Terraform install Kubernetes itself?
Terraform creates managed clusters through the cloud providers (EKS, GKE, AKS) and can provision VMs for self-managed clusters, but it does not install Kubernetes on its own. For local testing, kind or minikube is faster than any Terraform setup.
Drawing the line between Terraform and GitOps is a decision you live with for years, and it is easier to get right before the first hundred services. If you want a second opinion on your cluster bootstrap or a review of your Terraform layout, book a free consultation with our engineers.