

A Kubernetes Job runs a task to completion and tracks its Pods, so use one instead of a bare Pod for migrations, backfills and repairs. Set restartPolicy: Never, a low backoffLimit, activeDeadlineSeconds as a hard time limit, and ttlSecondsAfterFinished so Kubernetes deletes the finished Job and its Pods automatically.
One-off work usually happens during an incident or a release window, when someone needs a result fast and skips the cleanup path. That is how clusters collect completed Pods, duplicate migration attempts and unclear history. This guide shows the manifest, the commands and the cleanup rules that prevent it.
Job vs CronJob vs bare Pod
| Bare Pod | Job | CronJob | |
|---|---|---|---|
| Use it for | Interactive debugging only | One-off tasks: migrations, backfills, repairs | Recurring tasks on a schedule |
| Retries on failure | No (container restarts only) | Yes, up to backoffLimit (default 6) | Each run is a Job with its own retries |
| Records success or failure | Only the Pod phase | Yes, Job conditions Complete or Failed | Yes, per Job, plus history limits |
| Automatic cleanup | None | ttlSecondsAfterFinished | successfulJobsHistoryLimit (default 3) and failedJobsHistoryLimit (default 1) |
| Survives node failure | No | Yes, a new Pod is created elsewhere | Yes |
Use a Job instead of creating a Pod directly
A standalone Pod is a poor fit for work that should run once. If the Pod fails, Kubernetes does not provide the same completion and retry model that a Job provides. A Job creates and tracks Pods until its workload reaches the requested completion state.
For a one-off task, define these settings deliberately:
restartPolicy: Never: let the Job create a replacement Pod when the task fails instead of restarting the container inside the same Pod.backoffLimit: cap the number of failed attempts. Set this according to whether the command is safe to retry.completions: 1: make the intended result explicit when one successful completion is required.ttlSecondsAfterFinished: tell Kubernetes to remove the finished Job and its dependent Pods after the retention period.- A unique name: prevent a new run from colliding with an existing Job or making its status difficult to interpret.

Do not treat a Job as automatically safe to rerun. A migration or repair command may have side effects even when the container exits with a failure code. Confirm that the operation is idempotent, or add an application-level guard before increasing the retry limit.
Set automatic cleanup in the Job manifest
The most reliable cleanup path starts in the manifest. The following example keeps the finished Job and its Pods for one hour, permits no automatic retry, and uses a stable completion condition.
apiVersion: batch/v1
kind: Job
metadata:
  name: one-off-task
  namespace: default
spec:
  ttlSecondsAfterFinished: 3600
  backoffLimit: 0
  completions: 1
  parallelism: 1
  template:
    metadata:
      labels:
        app: one-off-task
    spec:
      restartPolicy: Never
      containers:
        - name: task
          image: registry.example.com/your-app:release
          command: ["/app/run-task"]
Apply the manifest and inspect the Job rather than deleting its Pod immediately:
kubectl apply -f one-off-job.yaml
kubectl get job one-off-task
kubectl get pods -l job-name=one-off-task
kubectl logs job/one-off-task
The retention value should match your operational needs. A short-lived diagnostic may need only a few minutes of access to logs. A production migration may need longer access for investigation. The cleanup timer starts after the Job reaches a finished state, so it does not remove an active task.

The TTL-after-finished controller has been stable since Kubernetes 1.23 and is on by default in EKS, GKE and AKS. If you run a custom control plane with the controller disabled, the Job and its Pods stay until something else removes them.
Cap runtime with activeDeadlineSeconds
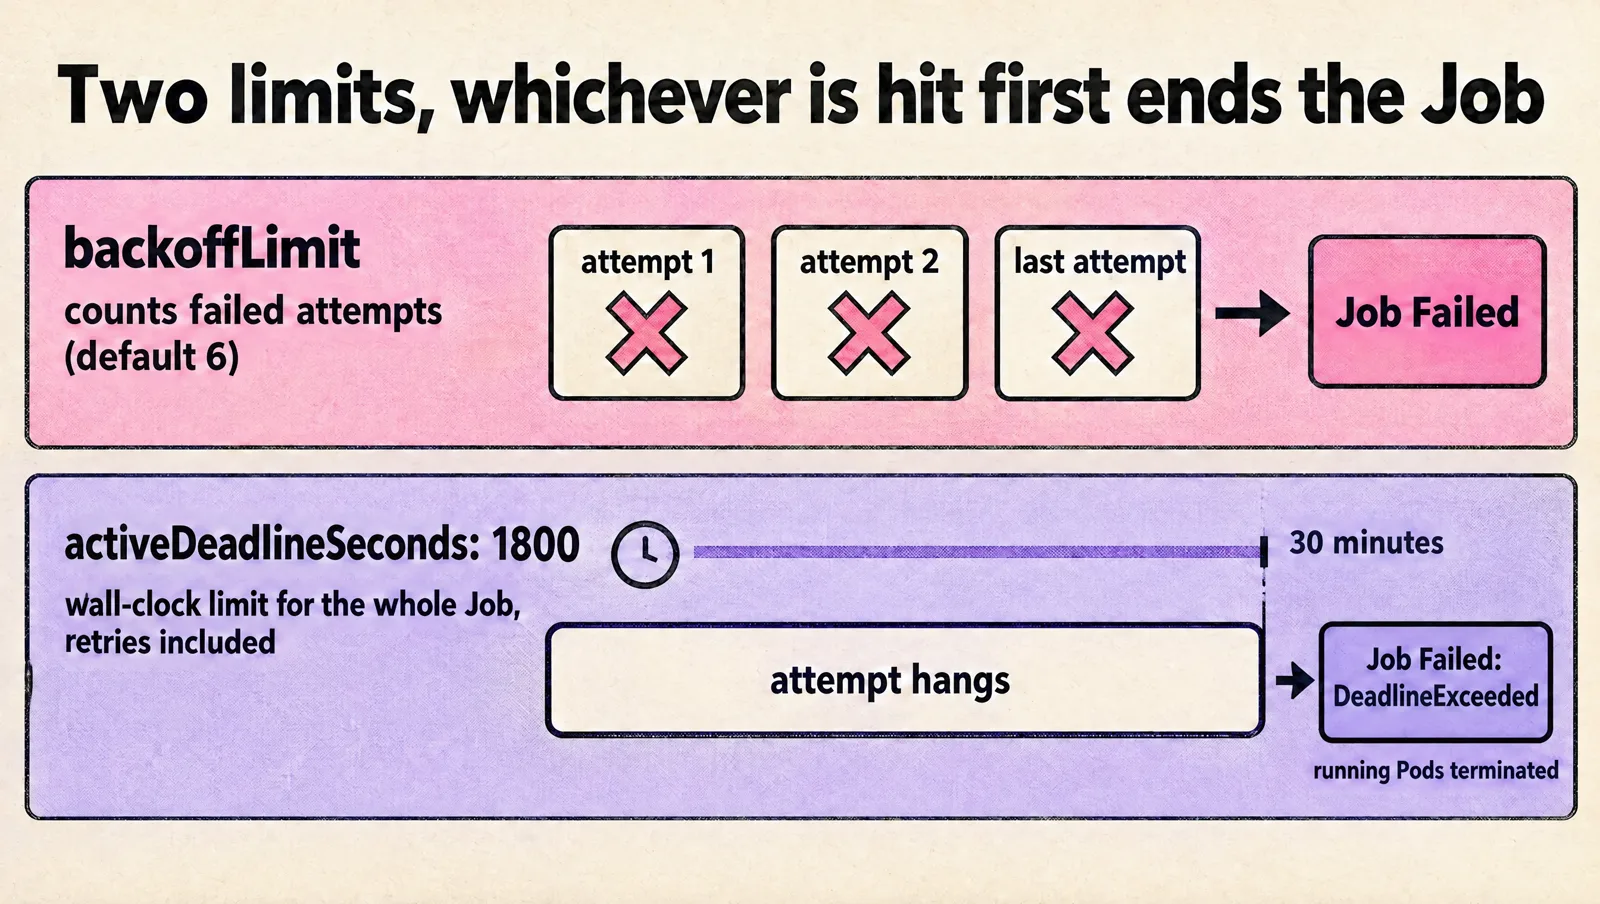
backoffLimit limits retries, but a single attempt can still hang forever (a stuck lock, an unreachable host). activeDeadlineSeconds sets a wall-clock limit for the whole Job, retries included. When it passes, Kubernetes terminates the running Pods and marks the Job Failed with reason DeadlineExceeded. It takes precedence over backoffLimit.
spec:
  activeDeadlineSeconds: 1800   # fail the Job after 30 minutes
  backoffLimit: 0
  ttlSecondsAfterFinished: 3600
To block until the Job finishes in a script or CI step, use kubectl wait:
kubectl wait --for=condition=complete job/one-off-task -n default --timeout=30mRun an ad hoc Job without losing its identity
For an interactive run, use a unique Job name and record the exact image, command, namespace, and requested cleanup period. Avoid reusing a name while an earlier attempt still exists. Kubernetes will reject the new object, and deleting the old one first can erase useful evidence.
kubectl create job one-off-task-20260906 \
  --image=registry.example.com/your-app:release \
  --namespace=default \
  -- /app/run-task
Run a CronJob once, right now
To trigger a CronJob outside its schedule (for example to test it or rerun a missed backup), create a Job from its template. The new Job inherits the CronJob's Pod spec:
kubectl create job backup-manual-20261022 --from=cronjob/nightly-backup -n defaultThe imperative command is convenient, but it does not express every policy you may need. Use a manifest when the task requires a cleanup timer, resource requests, environment variables, mounted credentials, a service account, or a carefully chosen retry policy. Store that manifest with the code or operational procedure so another engineer can reproduce the run.
Before starting the task, verify the namespace and current Jobs:
kubectl config current-context
kubectl get jobs -n default
kubectl get pods -n default
kubectl describe job one-off-task -n default
A unique name also improves incident review. You can distinguish a failed first attempt from a successful rerun instead of inferring history from a reused object.
Clean up explicitly when the run ends
Automatic cleanup is a safety net, not a substitute for an operator’s final check. Once you have captured the result and any required logs, remove the Job with its dependent Pods:
kubectl delete job one-off-task \
  --namespace=default \
  --cascade=foreground
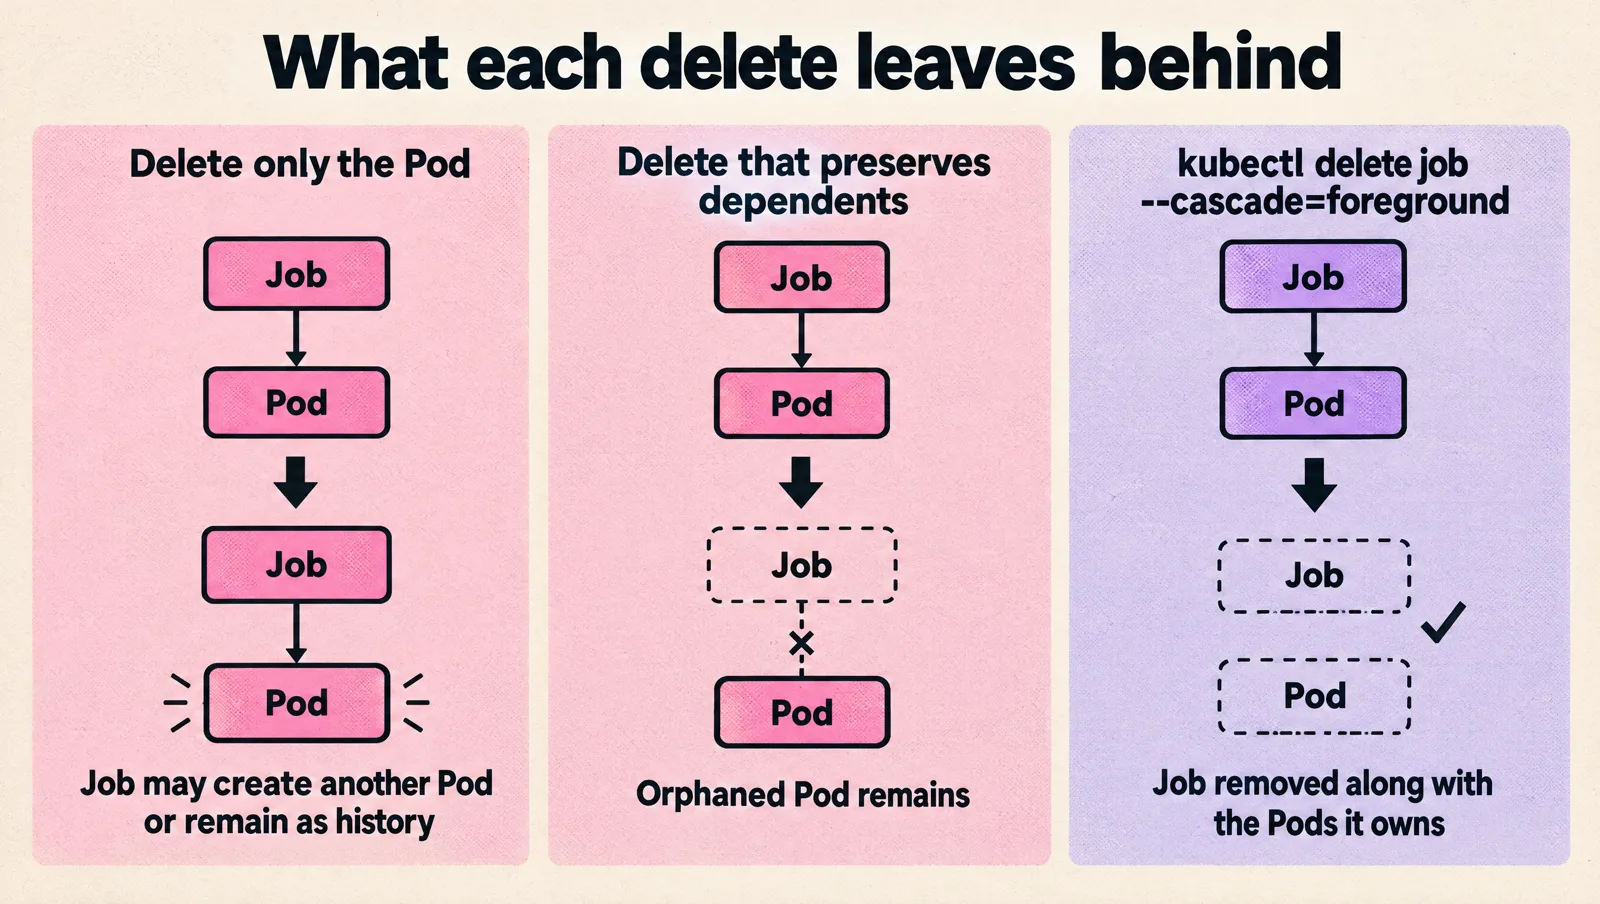
Foreground cascading deletion makes the dependency relationship explicit. The Job is removed along with the Pods it owns. If you need to keep the Job and its Pods for investigation, do not delete it yet. Instead, inspect its status and logs, then remove it after the investigation.
Be careful with deletion options that orphan dependents. A Pod can remain after its Job is deleted if the deletion request deliberately preserves dependent objects or if ownership metadata has been altered. That is a valid troubleshooting action in some cases, but it is the wrong default for routine one-off work.
After cleanup, verify both resource types:
kubectl get job one-off-task -n default
kubectl get pods -n default -l job-name=one-off-task
An empty result confirms that the named Job and its owned Pods no longer appear in that namespace. If a Pod remains, inspect its owner references and events before deleting it manually.
Prevent the failure modes that create clutter
Most orphaned or confusing Pods come from an incomplete operating procedure rather than from the Job controller itself. Check these conditions before and after each run:
- The command has no cleanup policy. Add
ttlSecondsAfterFinishedor define a documented deletion step. - The retry limit is too high. A non-idempotent command can create repeated side effects. Use
backoffLimit: 0when an operator must inspect the first failure. - The Job name is reused. Use a unique name for each attempt, especially during incident response.
- The operator deletes only the Pod. The Job may create another Pod or remain as completed history. Delete the Job when the whole run should be removed.
- The namespace is wrong. Always include
-nin commands used during production work. - Logs are needed after cleanup. Capture the logs and Job status before deletion, or set a retention period long enough for review.
- Labels are missing. Apply a task-specific label so you can inspect related resources without selecting unrelated Pods.
For teams that run these tasks frequently, standardize a small Job template and require the caller to provide the image, command, namespace, retention period, and retry policy. Platform teams managing larger clusters may also apply namespace-level policies or scheduled cleanup, but those controls should not hide an incorrectly configured one-off task.
A practical operating sequence
- Confirm that the command is safe to run once or safe to retry.
- Choose a unique Job name and the correct namespace.
- Set
backoffLimit,completions, andrestartPolicyexplicitly. - Set
ttlSecondsAfterFinishedto the period required for log and status review. - Apply the Job and watch the Job status, Pod status, and logs.
- Record the result before the retention timer removes the resources.
- Delete the Job with cascading deletion when you have finished reviewing it.
- Verify that no Job or Pod remains for that run.
Use this process for migrations, backfills, repairs, and diagnostics. The exact command will vary, but the resource lifecycle should remain predictable.
FAQ
What does ttlSecondsAfterFinished do?
It tells Kubernetes to delete a Job, and its Pods through cascading deletion, a set number of seconds after the Job completes or fails. A value of 0 deletes it immediately. It does not affect Jobs that are still running.
What is the difference between backoffLimit and activeDeadlineSeconds?
backoffLimit is the number of retries before the Job is marked failed (default 6). activeDeadlineSeconds is a time limit for the whole Job across all retries. Whichever is hit first ends the Job.
Why are completed Pods from my Job still in the cluster?
Without ttlSecondsAfterFinished and without deleting the Job, Kubernetes keeps finished Jobs and their Pods so you can read logs. Set a TTL, or delete the Job with kubectl delete job NAME, which removes its Pods too. Deleting only the Pod leaves the Job behind.
How do I run a CronJob manually?
Run kubectl create job NEW_NAME --from=cronjob/CRONJOB_NAME. It creates a one-off Job from the CronJob's template without changing the schedule.
Should restartPolicy be Never or OnFailure for a Job?
Use Never for one-off tasks: each failed attempt leaves a Pod with its logs for inspection, and the Job creates a fresh Pod for the retry. OnFailure restarts the container in the same Pod, which hides earlier failures. The Kubernetes Job documentation covers both.
Takeaway
Run one-off work as a Job, define its retry and completion behavior, and make cleanup part of the resource definition. Set a suitable ttlSecondsAfterFinished value, use unique names, inspect the outcome, and verify deletion. That combination keeps completed Pods available long enough to troubleshoot without allowing temporary operational work to become permanent cluster clutter.