

Argo Rollouts is a Kubernetes controller that replaces the standard Deployment with a Rollout resource that supports canary and blue-green releases. It shifts traffic to a new version in steps, runs automated analysis against metrics such as error rate, and rolls back on failure. Kubernetes alone offers only rolling updates.
This guide is the practical version: installing the controller with Helm, a canary with real traffic splitting and Prometheus analysis, a blue-green with a preview service, how it fits with Helm charts, the HPA and Argo CD, migrating an existing Deployment without downtime, and the failure modes that catch teams in their first month. The YAML is copy-paste ready and checked against Argo Rollouts v1.10.1, the current release in October 2026.
What Argo Rollouts does that a Deployment cannot
A Deployment's rolling update replaces pods gradually, but it has no notion of traffic percentage, no pause for a human or a metric check, and no automatic rollback when error rates climb. If the new pods pass readiness probes, Kubernetes considers the rollout a success even while users get errors.
Argo Rollouts adds four things:
- Steps. Send 5% of traffic, wait, check, send 25%, wait, check, and so on.
- Traffic control. With a traffic router (Gateway API, Istio, an ingress controller or AWS ALB) the weight is exact. Without one, it approximates the weight with the ratio of old to new pods.
- Analysis.
AnalysisTemplateresources query Prometheus, Datadog, CloudWatch, New Relic, a web endpoint or a Kubernetes Job, and promote or abort automatically. - Fast rollback. Aborting shifts traffic back to the stable ReplicaSet, which is still running.
Argo Rollouts vs Deployment vs Flagger
| Deployment (RollingUpdate) | Argo Rollouts | Flagger | |
|---|---|---|---|
| Resource you manage | Deployment | Rollout (or a Rollout that references your Deployment) | Your Deployment plus a Canary resource; Flagger generates a primary copy |
| Strategies | Rolling update, recreate | Canary, blue-green, experiments | Canary, blue-green, A/B testing |
| Metric analysis | None | AnalysisTemplates, many providers | Built-in checks (request success rate, duration) plus custom metrics |
| Manual gates | None | Indefinite pause and promote | Webhook-based gates |
| UI | None | kubectl plugin, dashboard, Argo CD integration | None of its own |
| Natural fit | Low-risk services | Teams on Argo CD wanting explicit, reviewable steps | Teams on Flux wanting automation with minimal manifest changes |
Plain Deployments are still the right answer for internal tools, workers and anything where a bad release is cheap to fix. Use Argo Rollouts for the user-facing services where a bad release costs money or trust.
Install Argo Rollouts
The Helm chart from the Argo project is the easiest way to keep the controller upgradable:
helm repo add argo https://argoproj.github.io/argo-helm
helm repo update
helm install argo-rollouts argo/argo-rollouts \
  --namespace argo-rollouts --create-namespace
Or with plain manifests:
kubectl create namespace argo-rollouts
kubectl apply -n argo-rollouts \
  -f https://github.com/argoproj/argo-rollouts/releases/latest/download/install.yaml
Then install the kubectl plugin, which you will use for status, promotion and abort:
# macOS
brew install argoproj/tap/kubectl-argo-rollouts

# Linux (amd64)
curl -LO https://github.com/argoproj/argo-rollouts/releases/latest/download/kubectl-argo-rollouts-linux-amd64
chmod +x kubectl-argo-rollouts-linux-amd64
sudo mv kubectl-argo-rollouts-linux-amd64 /usr/local/bin/kubectl-argo-rollouts

kubectl argo rollouts version
On GKE you may first need a cluster-admin role binding for your user so the install can create cluster roles. The chart's optional dashboard is disabled by default; enable it with --set dashboard.enabled=true if you want a web UI, or run kubectl argo rollouts dashboard locally.
Prepare the application first
Progressive delivery only protects users if the application can safely run two versions side by side. Check these before writing a single step:
- Honest readiness probes. A pod must not report ready until it can serve real requests. A TCP check that passes while caches load will send canary traffic to a pod that cannot handle it. Our guide to liveness and readiness probes covers the details.
- Graceful shutdown. Set
terminationGracePeriodSecondslong enough to finish in-flight requests, and add a shortpreStopsleep if your load balancer needs time to stop sending traffic. - Backward-compatible data changes. During a canary, old and new code share the database. Use expand and contract migrations: add columns before code uses them, remove them only after the old version is gone. Otherwise rollback is a pod rollback, not a data rollback.
- Spare capacity. Canary with traffic routing and blue-green both run old and new versions at full or near-full size at the same time. If the cluster cannot fit roughly double the pods, the rollout stalls in
Pendingunless a node autoscaler adds capacity. - Metrics per version. Analysis needs to tell canary errors from stable errors. Argo Rollouts labels pods with
rollouts-pod-template-hash, and with a traffic router you get separate canary and stable services to filter on.
Canary deployment with Argo Rollouts
Choose a traffic router
Without a traffic router, Argo Rollouts approximates the weight with pod counts: with 10 replicas, setWeight: 10 means one canary pod, and your Service spreads requests across all pods. That is fine for a first try but imprecise at low replica counts (you cannot send 5% of traffic with 4 replicas).

For exact weights, use a traffic router. Supported options include the Gateway API (through the official plugin), Istio, AWS ALB, NGINX Ingress, Traefik, Kong, Ambassador, Apache APISIX, Google Cloud and SMI. One important note for 2026: the community Ingress NGINX controller was retired in March 2026 and no longer receives releases or security fixes. For new setups, the Gateway API plugin is the forward-looking choice, and it works with any Gateway API implementation (Envoy Gateway, Istio, Cilium, NGINX Gateway Fabric and others).
Register the Gateway API plugin
Plugins are registered in the controller's config map (the plugin's current release is v0.17.0; pick the binary for your node architecture):
apiVersion: v1
kind: ConfigMap
metadata:
  name: argo-rollouts-config      # must be this name
  namespace: argo-rollouts        # must be this namespace
data:
  trafficRouterPlugins: |-
    - name: "argoproj-labs/gatewayAPI"
      location: "https://github.com/argoproj-labs/rollouts-plugin-trafficrouter-gatewayapi/releases/download/v0.17.0/gatewayapi-plugin-linux-amd64"
The controller's service account also needs get, patch and update on httproutes in the gateway.networking.k8s.io API group. The controller downloads plugins when it starts, so restart it after changing this config map. Note that the controller will not start at all if it cannot download the plugin, so for production consider shipping the binary through an init container (the Helm chart supports this) instead of fetching it from GitHub on every restart.
Services, route and Rollout
You need two Services that select the same pods (Argo Rollouts injects the ReplicaSet hash into their selectors during a rollout) and an HTTPRoute that sends traffic to both:
apiVersion: v1
kind: Service
metadata:
  name: api-stable
spec:
  selector:
    app: api
  ports:
    - name: http
      port: 80
      targetPort: http
---
apiVersion: v1
kind: Service
metadata:
  name: api-canary
spec:
  selector:
    app: api
  ports:
    - name: http
      port: 80
      targetPort: http
---
apiVersion: gateway.networking.k8s.io/v1
kind: HTTPRoute
metadata:
  name: api
spec:
  parentRefs:
    - name: public-gateway
      namespace: gateway
  hostnames:
    - api.example.com
  rules:
    - backendRefs:
        - name: api-stable
          port: 80
          weight: 100
        - name: api-canary
          port: 80
          weight: 0
The Rollout looks like a Deployment with a strategy block that describes the release:
apiVersion: argoproj.io/v1alpha1
kind: Rollout
metadata:
  name: api
spec:
  replicas: 6
  revisionHistoryLimit: 3
  selector:
    matchLabels:
      app: api
  template:
    metadata:
      labels:
        app: api
    spec:
      containers:
        - name: api
          image: registry.example.com/api:1.8.0
          ports:
            - name: http
              containerPort: 8080
          readinessProbe:
            httpGet:
              path: /ready
              port: http
          resources:
            requests:
              cpu: 250m
              memory: 256Mi
  strategy:
    canary:
      stableService: api-stable
      canaryService: api-canary
      trafficRouting:
        plugins:
          argoproj-labs/gatewayAPI:
            httpRoute: api
            namespace: default
      analysis:
        templates:
          - templateName: http-success-rate
        startingStep: 2
        args:
          - name: service
            value: api-canary
      steps:
        - setWeight: 5
        - pause: { duration: 5m }
        - setWeight: 25
        - pause: { duration: 10m }
        - setWeight: 50
        - pause: { duration: 10m }
        - setWeight: 100
How this plays out: Argo Rollouts creates the new ReplicaSet, points api-canary at it, sets the HTTPRoute weights to 95/5, and waits 5 minutes. From step index 2 (the 25% step) it starts a background analysis that runs until the rollout finishes. If the analysis fails, the rollout aborts and the weight returns to 0. With traffic routing, the stable ReplicaSet stays fully scaled throughout, which is what makes the abort instant.
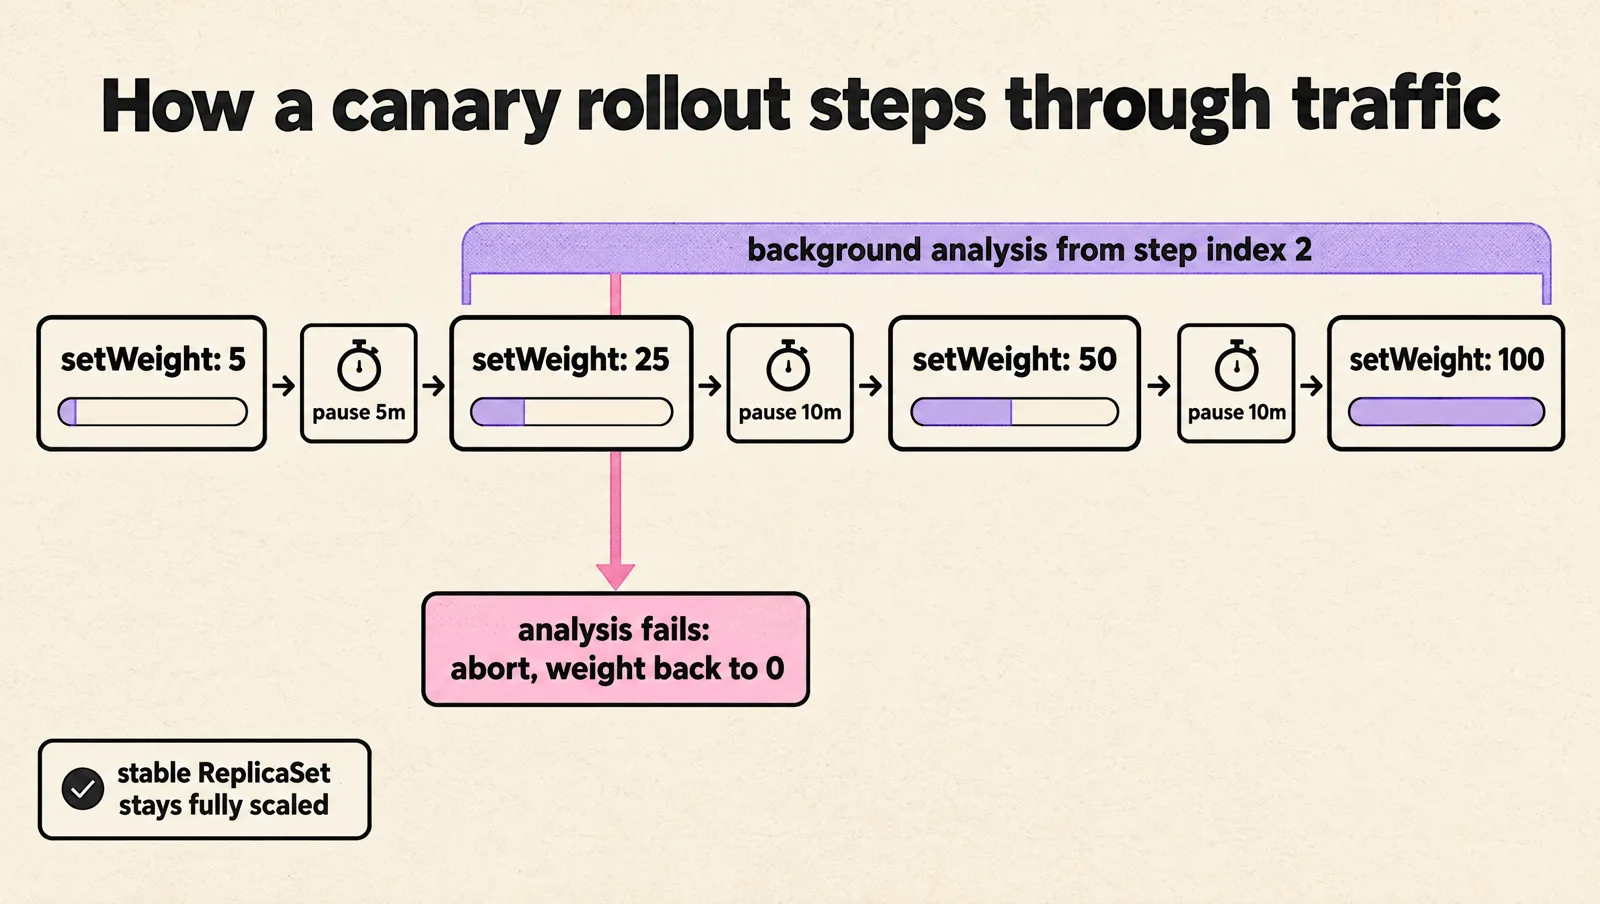
If running double capacity is too expensive, set dynamicStableScale: true under canary to scale the stable side down as weight shifts. The tradeoff: an abort then has to scale the stable side back up before it can take all the traffic.
Manual gates
A pause without a duration waits forever, which is how you add a human approval step:
steps:
  - setWeight: 10
  - pause: {}          # wait for: kubectl argo rollouts promote api
  - setWeight: 50
  - pause: { duration: 10m }
Automated analysis with Prometheus
An AnalysisTemplate defines what "healthy" means. This one checks that at least 99% of canary requests in the last 5 minutes were not 5xx, measured every minute, and fails the rollout after 2 bad measurements. Adapt the query to the metric names your services or gateway expose:
apiVersion: argoproj.io/v1alpha1
kind: AnalysisTemplate
metadata:
  name: http-success-rate
spec:
  args:
    - name: service
  metrics:
    - name: success-rate
      interval: 1m
      failureLimit: 2
      successCondition: len(result) == 0 || result[0] >= 0.99
      provider:
        prometheus:
          address: http://prometheus-server.monitoring.svc:80
          query: |
            sum(rate(http_requests_total{service="{{args.service}}",code!~"5.."}[5m]))
            /
            sum(rate(http_requests_total{service="{{args.service}}"}[5m]))
Things worth knowing about analysis:
- Background vs inline.
strategy.canary.analysisruns in the background across steps. An- analysis:entry insidestepsruns once at that point and blocks until it finishes; without anintervalit takes a single measurement. - Prometheus returns a vector. Index into it with
result[0]. Guard against empty results (no traffic yet), or a quiet canary fails for the wrong reason. - Inconclusive pauses. If a measurement matches neither the success nor the failure condition, the run is
Inconclusiveand the rollout pauses for a human decision. That is useful when you are still learning which thresholds make sense. - Dry run first. Setting a metric to dry-run mode records results without aborting, so you can calibrate a new check against real releases before trusting it.
- Share templates. A
ClusterAnalysisTemplatecan be used by Rollouts in any namespace; reference it withclusterScope: true.
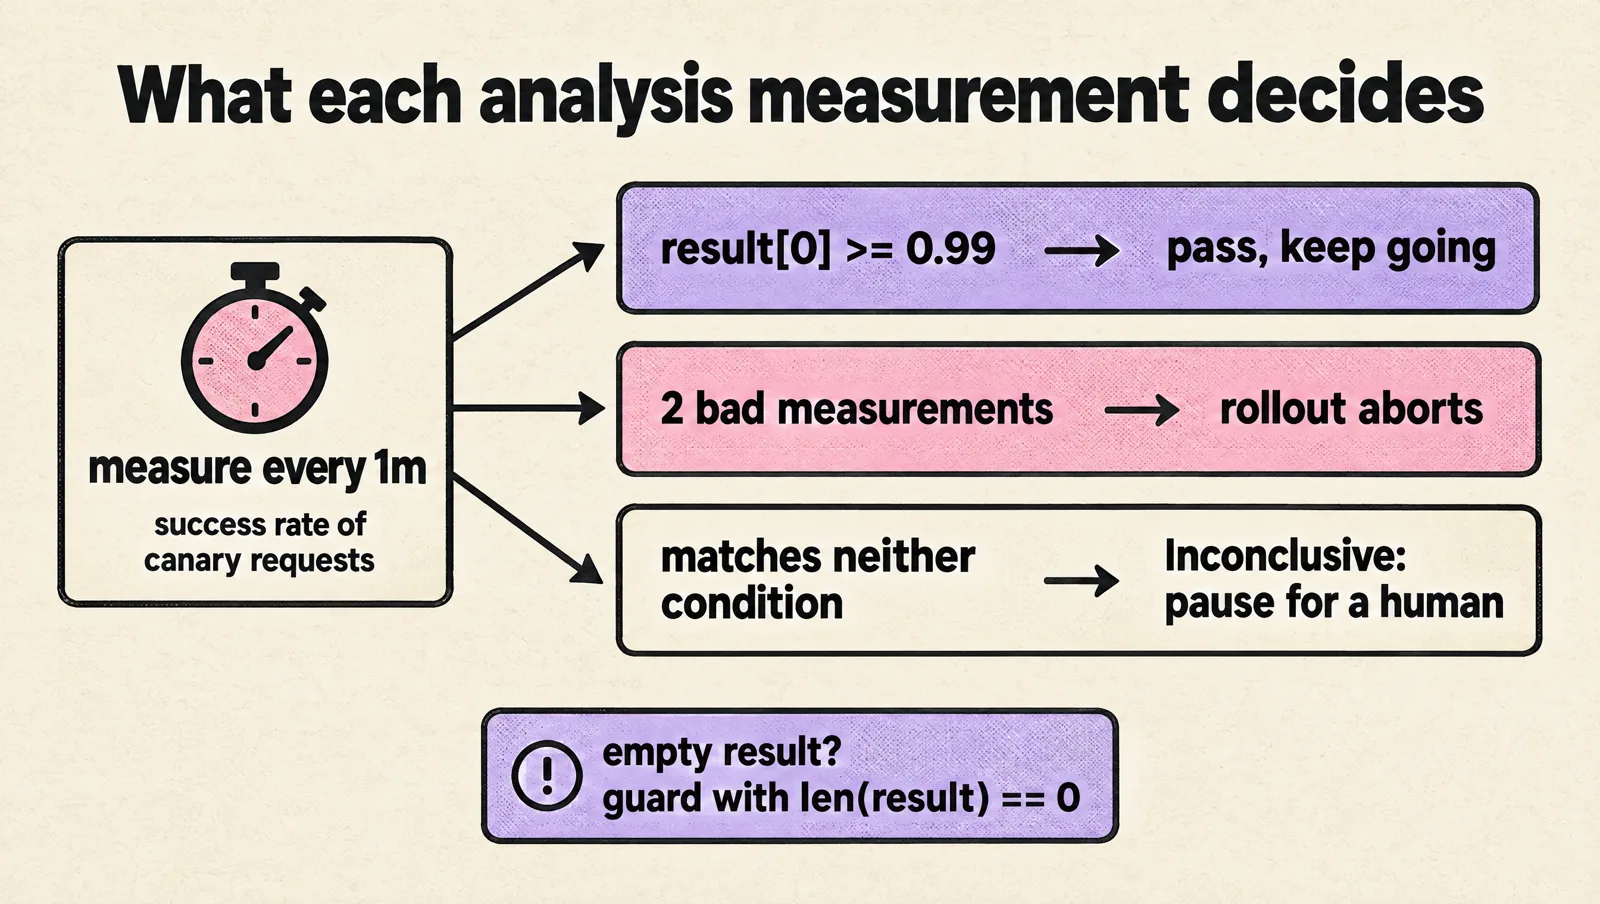
Start with two signals your team already trusts during incidents, usually error rate and p95 latency. A noisy check that blocks good releases gets disabled within a month, and then you have no check at all.
Blue-green deployment with Argo Rollouts
Blue-green runs the full new version beside the old one, lets you test it through a preview service, then switches all traffic at once:
apiVersion: argoproj.io/v1alpha1
kind: Rollout
metadata:
  name: web
spec:
  replicas: 4
  revisionHistoryLimit: 3
  selector:
    matchLabels:
      app: web
  template:
    metadata:
      labels:
        app: web
    spec:
      containers:
        - name: web
          image: registry.example.com/web:3.2.0
          ports:
            - containerPort: 8080
  strategy:
    blueGreen:
      activeService: web-active
      previewService: web-preview
      autoPromotionEnabled: false
      prePromotionAnalysis:
        templates:
          - templateName: smoke-tests
      scaleDownDelaySeconds: 60
The sequence: the new ReplicaSet starts and web-preview points at it while web-active still serves users. Once it is fully available, the pre-promotion analysis (for example, a Job that runs smoke tests against the preview service) must pass. Because autoPromotionEnabled is false, the rollout then waits for kubectl argo rollouts promote web. After promotion, web-active switches to the new pods, and the old ReplicaSet keeps running for scaleDownDelaySeconds (30 seconds by default) so nodes have time to update their routing rules.
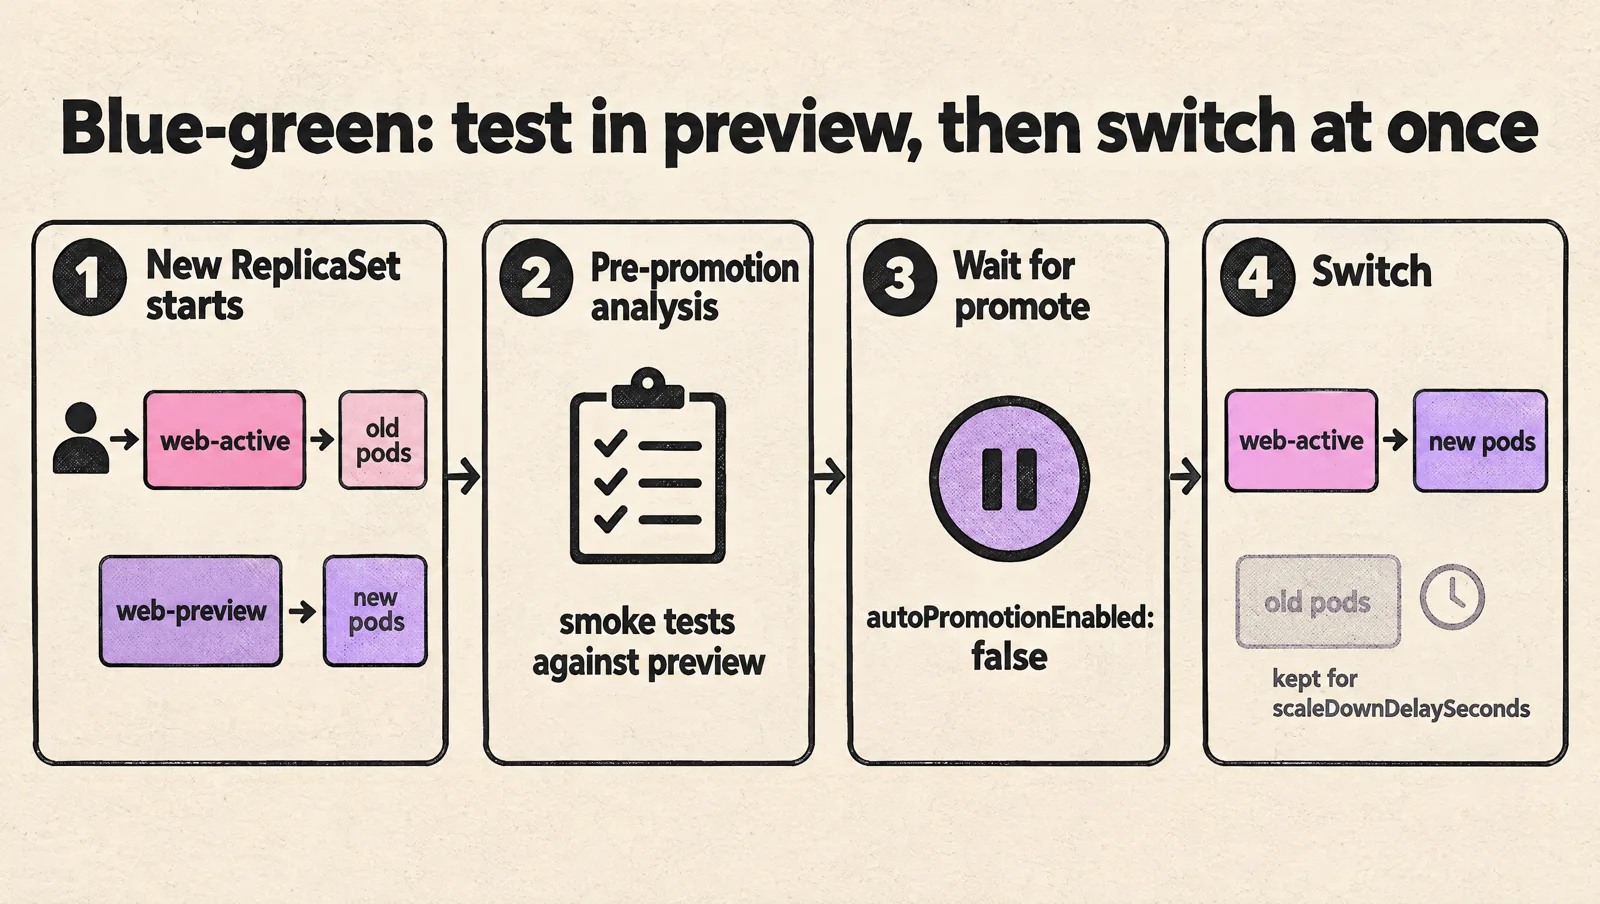
Two blue-green specifics:
autoPromotionEnableddefaults totrue, which promotes as soon as the new pods are ready. Set it tofalseor useautoPromotionSecondsif you want a window to test the preview.- The Argo Rollouts docs warn that blue-green behind the AWS Load Balancer Controller (ALB ingress) can cause downtime, because target groups are not updated atomically. On ALB, prefer canary with ALB traffic routing.
Canary or blue-green?
| Question | Canary | Blue-green |
|---|---|---|
| Want to limit how many users see a bad release? | Yes, 5% or less | No, everyone switches at once |
| Need to test the full new stack before any user traffic? | Partly, with header routing (Istio) | Yes, through the preview service |
| Extra capacity during release | Up to double with traffic routing, less with dynamicStableScale | Double, unless previewReplicaCount is set |
| Needs a traffic router for precision | Yes | No, it switches Service selectors |
| Best for | High-traffic APIs where metrics reveal problems quickly | Lower-traffic apps, release windows, apps that need smoke tests |
Argo Rollouts with Helm, the HPA and Argo CD
Helm
Argo Rollouts reacts to changes to a Rollout no matter how they are applied, so a Helm chart simply templates a Rollout instead of a Deployment. Keep the release behavior in values so a reviewer can see it:
# values-production.yaml
image:
  repository: registry.example.com/api
  tag: "1.8.0"
rollout:
  canarySteps:
    - setWeight: 5
    - pause: { duration: 5m }
    - setWeight: 25
    - pause: { duration: 10m }
- setWeight: 100# templates/rollout.yaml (excerpt)
strategy:
canary:
stableService: {{ include "api.fullname" . }}-stable
canaryService: {{ include "api.fullname" . }}-canary
steps:
{{- toYaml .Values.rollout.canarySteps | nindent 8 }}The catch: helm upgrade returns as soon as the Rollout object is updated, long before the canary finishes. In CI, wait on the rollout itself so the pipeline reflects the real outcome:
helm upgrade --install api ./chart -n production -f values-production.yaml
kubectl argo rollouts status api -n production --timeout 45m
The status command exits non-zero if the rollout is aborted or degraded, so the pipeline fails when the release fails.
Horizontal Pod Autoscaler
Rollouts expose the same /scale subresource as Deployments, so the HPA works by targeting the Rollout:
spec:
  scaleTargetRef:
    apiVersion: argoproj.io/v1alpha1
    kind: Rollout
    name: api
The HPA decides the total replica count and Argo Rollouts splits it between stable and canary according to the current step. Remove spec.replicas from the manifest (or ignore it in your GitOps tool) so deploys do not fight the HPA. Our Kubernetes HPA guide covers the tuning, including why startup CPU from canary pods can trigger extra scale ups.
Argo CD and GitOps
Argo CD understands Rollout health and ships resource actions for it (resume, promote-full, abort, retry, pause, restart and skip-current-step), so engineers can drive releases from the Argo CD UI. Two GitOps rules prevent confusion:
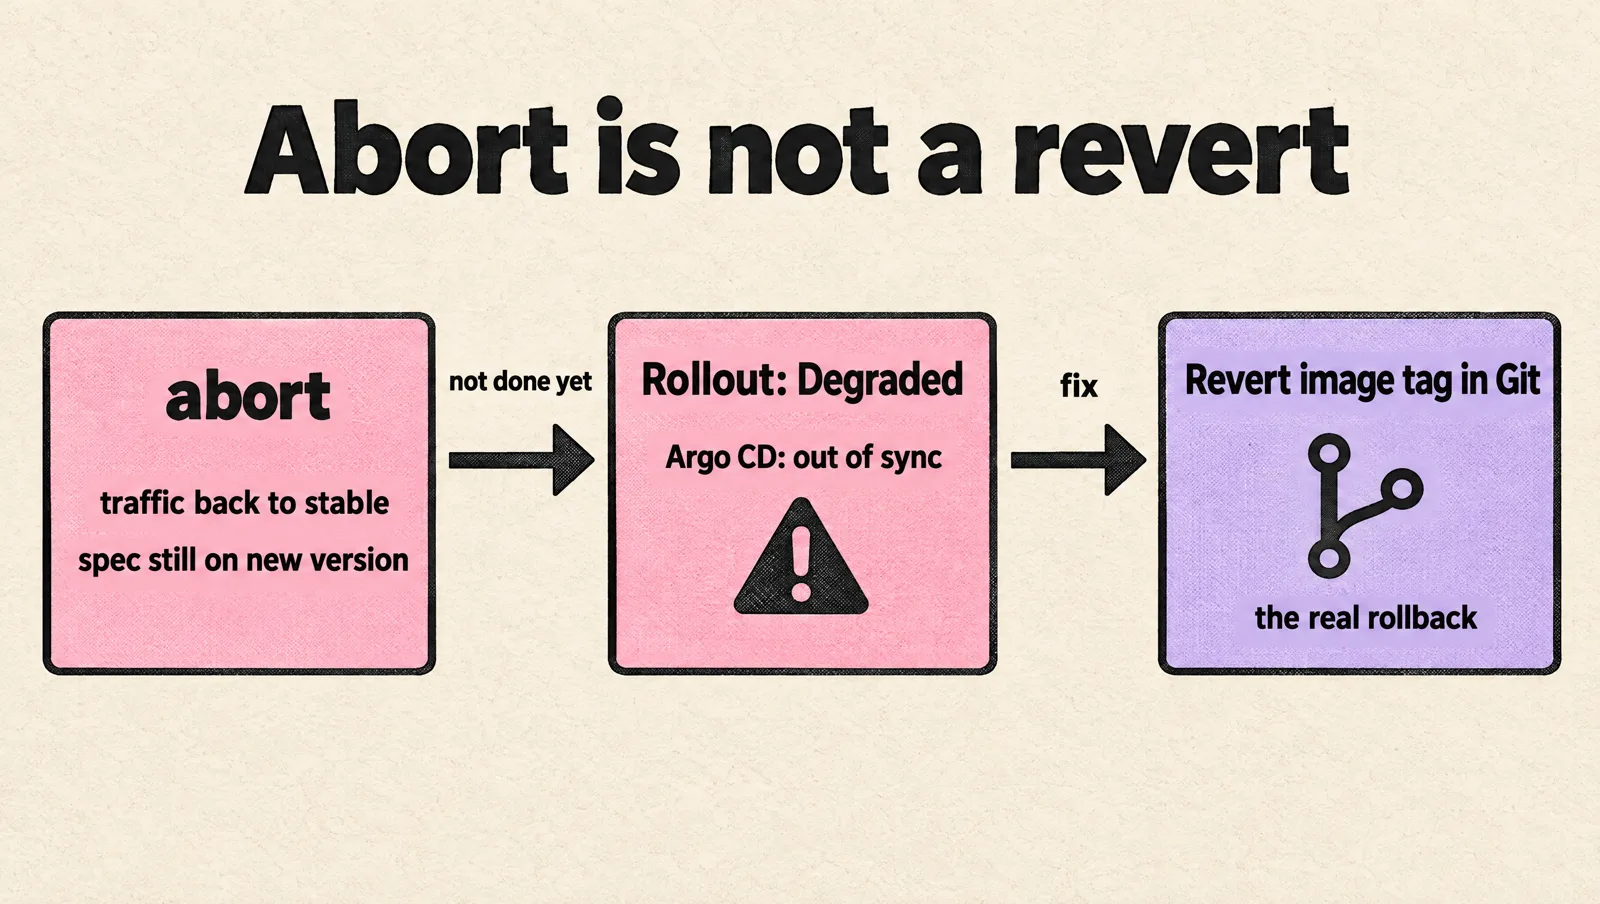
- Abort is not a revert. After
abort, traffic goes back to stable, butspec.templatestill describes the new version and the Rollout showsDegraded. The real rollback is reverting the image tag in Git. Until you do, Argo CD reports the app as out of sync or degraded. - Fast rollbacks need a window. Re-applying an older version normally replays all steps and analysis. Setting
rollbackWindow.revisionslets the controller skip steps when rolling back to a recent revision.
If you are deciding whether GitOps is worth adopting at all, see our breakdown of GitOps benefits and challenges.
Migrate an existing Deployment without downtime
You do not have to delete your Deployment to adopt Argo Rollouts. A Rollout can reference it with workloadRef and take over its pod template:
apiVersion: argoproj.io/v1alpha1
kind: Rollout
metadata:
  name: api
spec:
  replicas: 6
  selector:
    matchLabels:
      app: api
  workloadRef:
    apiVersion: apps/v1
    kind: Deployment
    name: api
    scaleDown: progressively   # or: onsuccess, never
  strategy:
    canary:
      steps:
        - setWeight: 20
        - pause: { duration: 5m }
progressively scales the Deployment down as the Rollout scales up, so capacity never dips. onsuccess waits until the Rollout is healthy, and never leaves the Deployment alone. Future changes go to the Deployment's pod template, and the Rollout releases them with its strategy. Once you are confident, you can move the template into the Rollout and delete the Deployment.
Day-two commands
kubectl argo rollouts get rollout api -n production --watch   # live tree of ReplicaSets, steps, analysis
kubectl argo rollouts set image api api=registry.example.com/api:1.8.1 -n production
kubectl argo rollouts promote api -n production               # continue past a pause
kubectl argo rollouts promote api --full -n production        # skip remaining steps and analysis
kubectl argo rollouts abort api -n production                 # send traffic back to stable
kubectl argo rollouts retry rollout api -n production         # retry an aborted rollout
kubectl argo rollouts undo api --to-revision=3 -n production  # roll back to an older revision
kubectl argo rollouts restart api -n production               # restart pods safely
Prefer changing the image in Git over set image if Argo CD or Flux manages the Rollout, or the next sync will undo your change.
Common Argo Rollouts problems and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
Rollout stuck at the first step with pods Pending | No room for the extra ReplicaSet | Add node autoscaling, lower canary scale, or use dynamicStableScale |
| Weight says 5% but traffic looks like 25% | No traffic router; weight is approximated by pod count | Add a traffic router or raise replicas so the ratio can be met |
Rollout Degraded after an abort, Argo CD out of sync | The spec still points at the bad version | Revert the image tag in Git |
| Analysis fails on a quiet service | Empty Prometheus result or too few requests | Guard with len(result) == 0, use longer windows, or generate test traffic |
| Canary passes but users still hit errors after promotion | The check measured the wrong service, or the problem only appears at full load | Filter metrics by the canary service or pod hash; add a post-100% pause with analysis |
| Replica count resets on every deploy | spec.replicas in Git fights the HPA | Remove it from the manifest when an HPA is attached |
| Brief errors during blue-green switch on AWS | ALB target group updates are not atomic | Use canary with ALB traffic routing |
| Traffic plugin not working after install | Controller not restarted, wrong architecture binary, or missing HTTPRoute RBAC | Check controller logs, the plugin URL and the role binding |
Rollout readiness checklist
- Readiness probes reflect real readiness and shutdown is graceful.
- Database changes are backward compatible with the previous version.
- The cluster can absorb the extra pods during a release.
- A traffic router is configured if you need precise weights below 25%.
- At least one analysis metric, filtered to the canary, with a calibrated threshold.
- CI waits on
kubectl argo rollouts status, not just on Helm. - Everyone knows who can promote and abort, and that rollback means reverting Git.
- The HPA, if any, targets the Rollout and
spec.replicasis not in the manifest.
Argo Rollouts FAQ
What is an Argo Rollout?
A Rollout is a custom resource provided by the Argo Rollouts controller. It has the same pod template as a Deployment, plus a strategy section that describes canary or blue-green steps, traffic routing and analysis.
What is the difference between Argo CD and Argo Rollouts?
Argo CD syncs what is in Git to the cluster. Argo Rollouts controls how a new version replaces the old one once it reaches the cluster. They are separate projects that work well together: Argo CD applies the Rollout, Argo Rollouts runs the release, and Argo CD shows its health.
Do I need a service mesh for Argo Rollouts?
No. Basic canary works with plain Services by adjusting pod counts, and blue-green needs no router at all. For precise traffic weights you need a traffic router, which can be the Gateway API, an ingress controller or AWS ALB rather than a full mesh.
How do I restart an Argo Rollout?
Run kubectl argo rollouts restart <name>. It recreates pods gradually without changing the spec, similar to kubectl rollout restart for Deployments.
Does Argo Rollouts work with the HPA?
Yes. Point the HPA's scaleTargetRef at the Rollout. The HPA sets the total replicas, and Argo Rollouts distributes them between stable and canary.
How does rollback work?
abort immediately returns traffic to the stable ReplicaSet. To finish the rollback, change the pod template back to the previous version, usually by reverting the commit in Git. kubectl argo rollouts undo does the same thing imperatively.
Is Argo Rollouts production ready?
Yes. It is part of the Argo project, a graduated project of the Cloud Native Computing Foundation (CNCF), and it is widely run in production. The main risks are in the application (probes, migrations, metrics), not the controller.
Progressive delivery pays off fastest when it is set up once as a reusable pattern rather than service by service. MeteorOps engineers build this for startups as part of our Argo Rollouts and Kubernetes work.