

To expand a PersistentVolumeClaim without taking the workload offline, confirm the StorageClass has allowVolumeExpansion: true and the CSI driver supports online expansion, then raise spec.resources.requests.storage on the PVC. The driver grows the volume and the kubelet grows the filesystem while the pod keeps running. Verify with df -h inside the pod.
kubectl patch pvc data-postgres-0 -n production \
  -p '{"spec":{"resources":{"requests":{"storage":"200Gi"}}}}'
The command is one line. The safe part is proving every layer supports the change, handling StatefulSets (whose volumeClaimTemplates cannot be edited in place), and keeping GitOps from fighting you. This guide covers all three.
Every layer a PVC resize touches
| Layer | What must be true | How to check |
|---|---|---|
| StorageClass | allowVolumeExpansion: true | kubectl get sc STORAGECLASS -o jsonpath='{.allowVolumeExpansion}' |
| CSI driver | Supports expansion, ideally online (while attached) | Driver docs; kubectl get csidriver |
| Cloud volume | Within provider limits (for example, an EBS volume can be modified only once every 6 hours) | Provider console or API |
| Filesystem | ext4 or XFS grow online; nothing shrinks | kubectl exec POD -- df -h MOUNT |
| Source of truth | Git, Helm values or Terraform show the new size | Your repo and the next sync diff |
What has to support online expansion
A PVC resize touches several layers. Kubernetes accepts the request, the storage driver expands the underlying volume, the node makes the new size available to the pod, and the filesystem grows inside the mounted volume. Any weak link can turn a simple storage change into an incident.
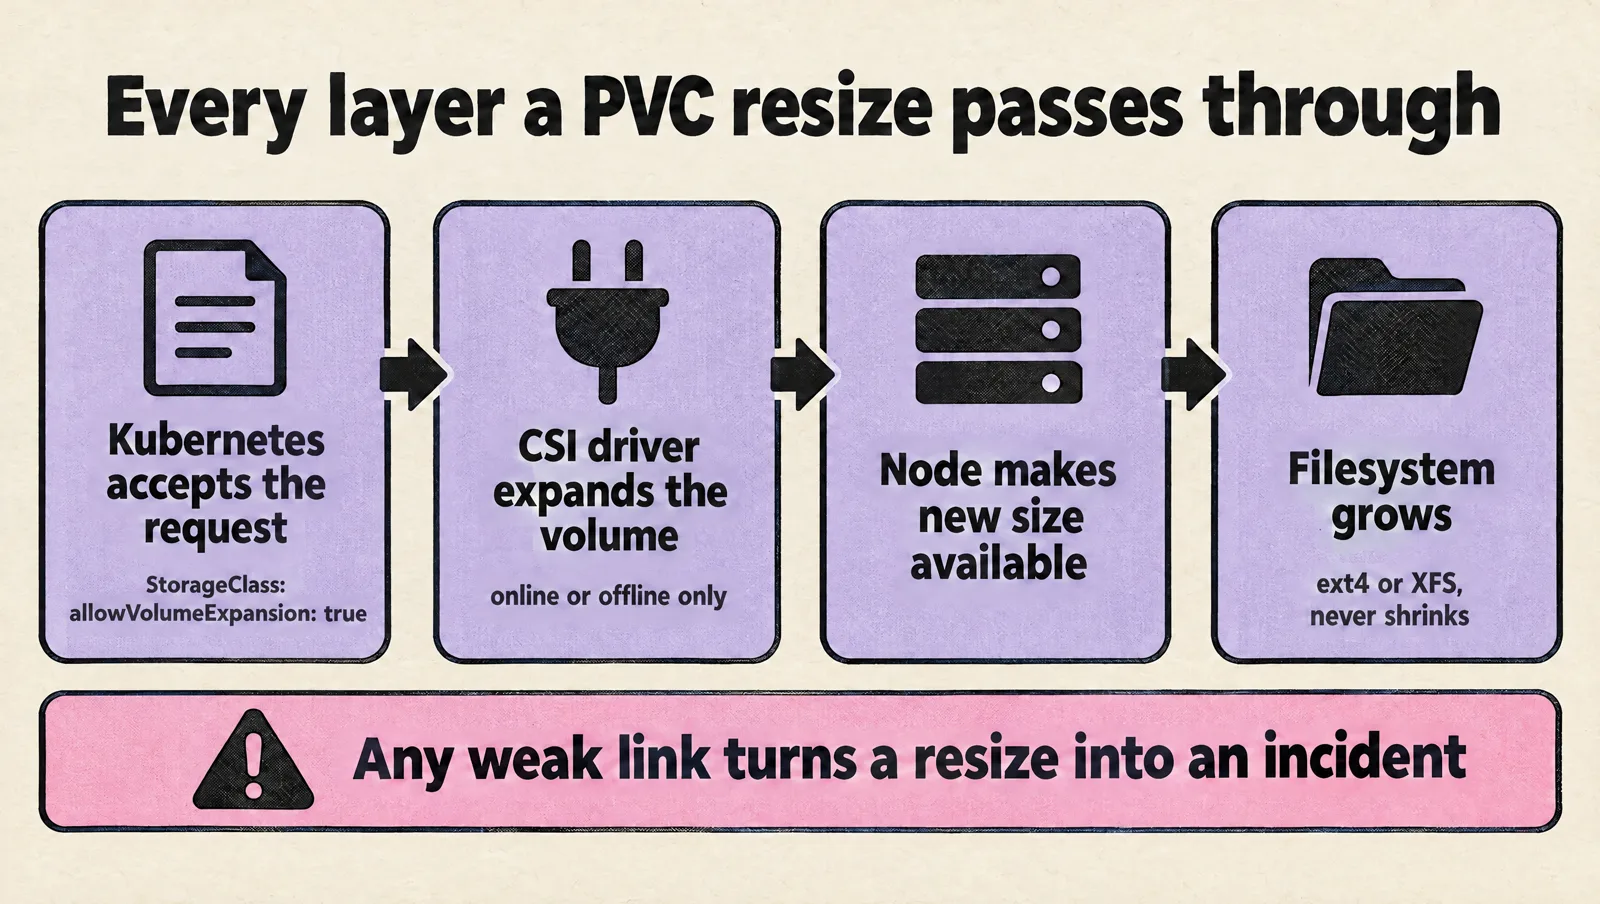
Before resizing a production PVC, check these requirements:
- The StorageClass allows expansion. The StorageClass must set
allowVolumeExpansion: true. Without this, Kubernetes rejects the PVC update. - The CSI driver supports expansion. The driver needs to support volume expansion for the storage backend you use. Some drivers support offline expansion only, while others support expansion while the volume is attached.
- The filesystem supports online growth. Common Linux filesystems such as ext4 and XFS support online expansion in typical Kubernetes setups. Shrinking is a different problem and is not supported through PVC resize.
- The workload can keep running during the change. A stateless pod with a cache behaves differently from a single-writer database. Your application should tolerate the storage layer changing size while the mount stays active.
- Your delivery process will not revert the patch. Helm, Kustomize, Terraform, Pulumi, Argo CD, Flux, or another controller may re-apply the old value if your desired state is stale.
If you are still standardizing your cluster patterns, it is worth treating this as part of broader Kubernetes platform design rather than a one-off emergency task. Storage classes, backup policy, pod disruption budgets, and deployment automation all affect how safe this operation feels under pressure.
Preflight checks before you touch the PVC
Start by identifying the PVC, StorageClass, PV, pod, node, and application owner. The worst time to discover that a volume backs a primary database is after you have already changed production state.
Use these checks before making the resize:
- Confirm current usage. Check filesystem usage from inside the pod with
df -h, and compare it with application-level metrics if you have them. - Check the PVC and PV. Review requested size, bound volume, access mode, volume mode, and StorageClass.
- Check the StorageClass. Confirm
allowVolumeExpansionis enabled. - Check driver behavior. Read the CSI driver documentation for online versus offline expansion and any provider-specific limits.
- Check backups and recovery. Make sure a recent backup or snapshot exists and that the team knows how to restore it.
- Check automation drift. Find the source of truth for the PVC size before changing it. If Git says 100Gi and the cluster says 200Gi, your next sync may undo expectations even if it cannot shrink the actual volume.
These checks are especially important in multi-cluster environments where storage classes may share names but behave differently. Teams that manage many production clusters often need consistent infrastructure patterns, as shown in work to simplify AWS and Kubernetes infrastructure management.
Resize the PVC safely
For a supported online expansion, the operational flow is simple: update the PVC storage request to a larger value, watch Kubernetes reconcile the change, then verify the filesystem inside the pod sees the new size.
First, inspect the PVC:
kubectl get pvc -n production
kubectl describe pvc data-postgres-0 -n production
Then patch the PVC with the new requested size. You can only increase the value.
kubectl patch pvc data-postgres-0 \
  -n production \
  -p '{"spec":{"resources":{"requests":{"storage":"200Gi"}}}}'
Watch the PVC status and events:
kubectl get pvc data-postgres-0 -n production -w
kubectl describe pvc data-postgres-0 -n production
Depending on the driver and Kubernetes version, you may see conditions such as FileSystemResizePending. That usually means the underlying volume has expanded, but the filesystem expansion still needs to complete on the node. With online expansion support, this often resolves while the pod keeps running. With offline-only behavior, you may need to restart the pod or let a controlled reschedule happen.
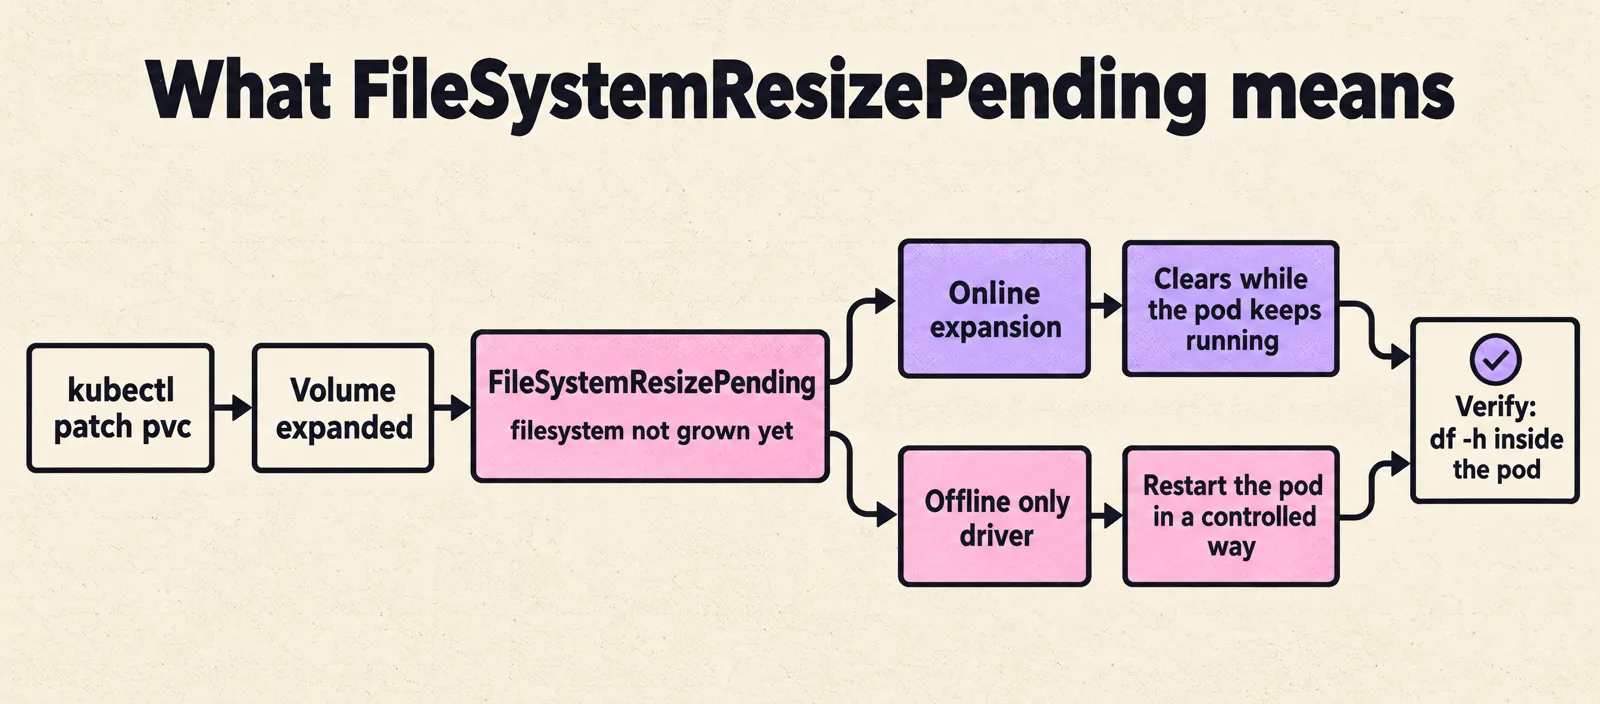
Finally, verify from inside the running pod:
kubectl exec -n production postgres-0 -- df -hThe PVC request, PV capacity, and filesystem size should all match your intended state or be in the expected reconciliation path. If the application exposes disk metrics, confirm those too. A clean Kubernetes object state does not always prove the application can use the added space.
StatefulSets, GitOps, and desired state traps
Stateful workloads add a few practical wrinkles. A StatefulSet often creates PVCs from volumeClaimTemplates, but existing PVCs are separate objects after creation. In many Kubernetes versions and setups, you cannot simply update the StatefulSet template and expect existing claims to resize. You usually patch each PVC directly.
For example, a database StatefulSet with three replicas may have PVCs like:
data-postgres-0data-postgres-1data-postgres-2
If all three need more space, resize each PVC intentionally. Do not assume that changing a chart value will update existing PVCs. It may only affect new claims, or it may fail because the StatefulSet field is immutable.
Workaround: resize StatefulSet volumes and keep the template in sync
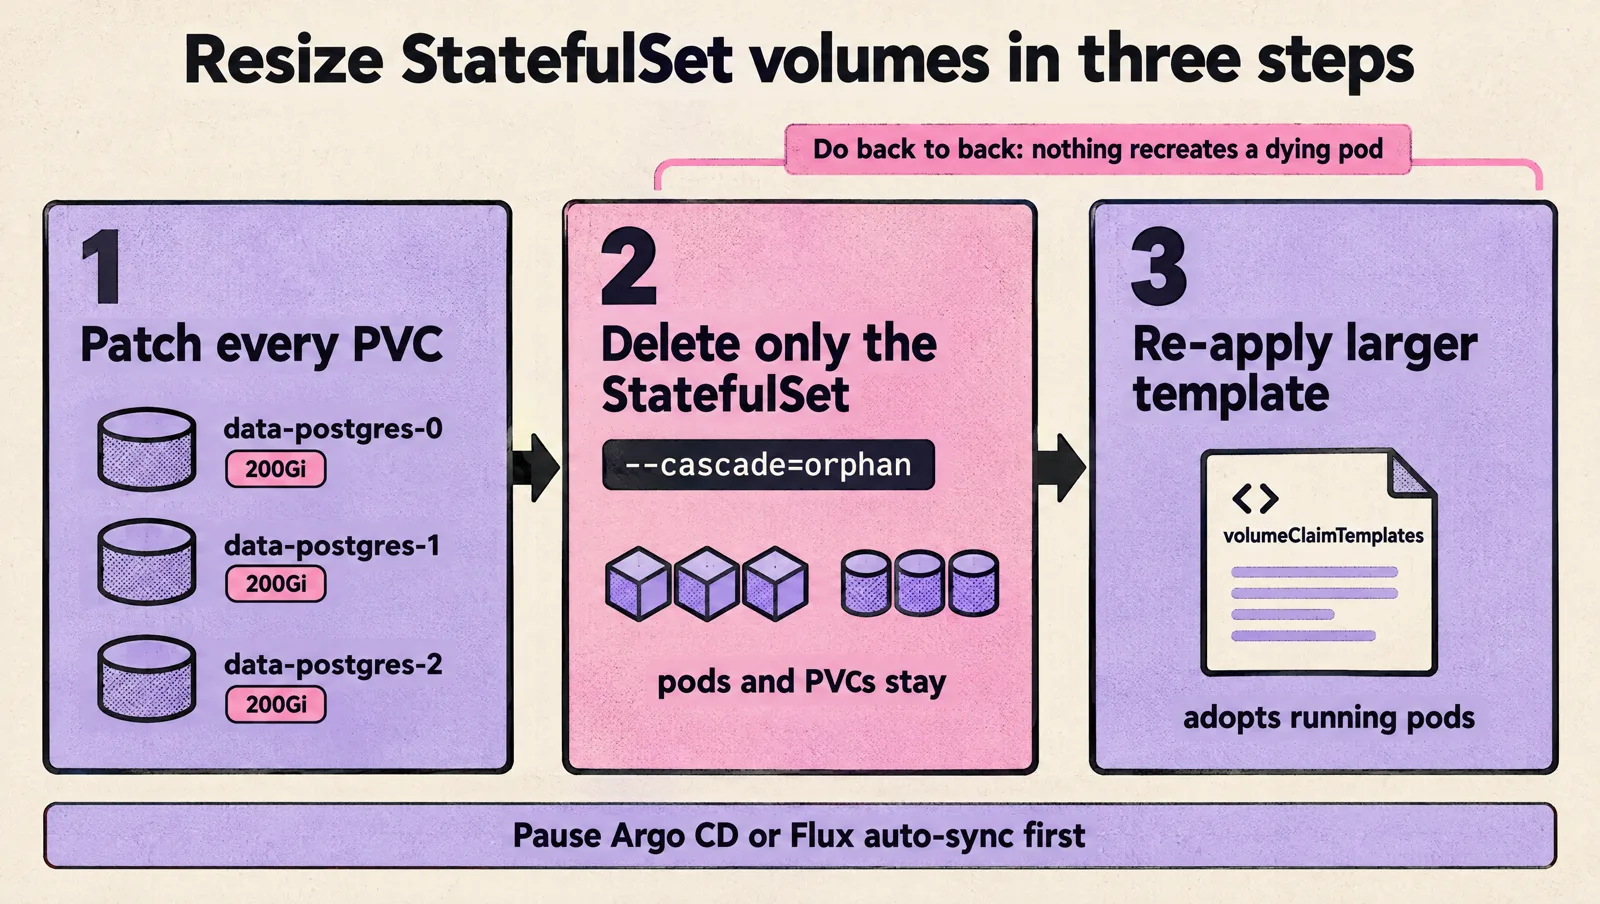
Editing volumeClaimTemplates on a live StatefulSet fails with spec: Forbidden: updates to statefulset spec for fields other than 'replicas', 'ordinals', 'template', 'updateStrategy', 'persistentVolumeClaimRetentionPolicy' and 'minReadySeconds' are forbidden. The standard workaround keeps the pods running:
- Patch every existing PVC to the new size and wait until each pod sees it:
for i in 0 1 2; do kubectl patch pvc data-postgres-$i -n production \ -p '{"spec":{"resources":{"requests":{"storage":"200Gi"}}}}' done - Delete only the StatefulSet object, leaving its pods and PVCs in place:
kubectl delete statefulset postgres -n production --cascade=orphan - Change the size in
volumeClaimTemplatesin your manifest or chart values and re-apply it. The new StatefulSet adopts the running pods, and future replicas get the larger size.
While the StatefulSet object is gone, nothing recreates a pod that dies, so do steps 2 and 3 back to back. If Argo CD or Flux manages the StatefulSet, pause auto-sync first so it does not recreate the object with the old template.
GitOps and infrastructure as code add another layer. If your PVCs are declared in Git, update the source of truth before or immediately after the live patch. If your PVCs were created by a Helm chart, check whether the chart manages PVC resources directly or only the StatefulSet template. If your platform uses Pulumi, Terraform, or another tool, make sure the tool understands the live resize instead of treating it as drift. Large cluster migrations and imports, such as efforts to import high-scale Kubernetes clusters into Pulumi, often expose these ownership problems.
A practical pattern is to record the resize in the same place your team records production changes:
- The old and new PVC size
- The namespace, PVC name, workload, and cluster
- The StorageClass and CSI driver
- The commands or pull request used
- The validation result after expansion
Failure modes to plan for
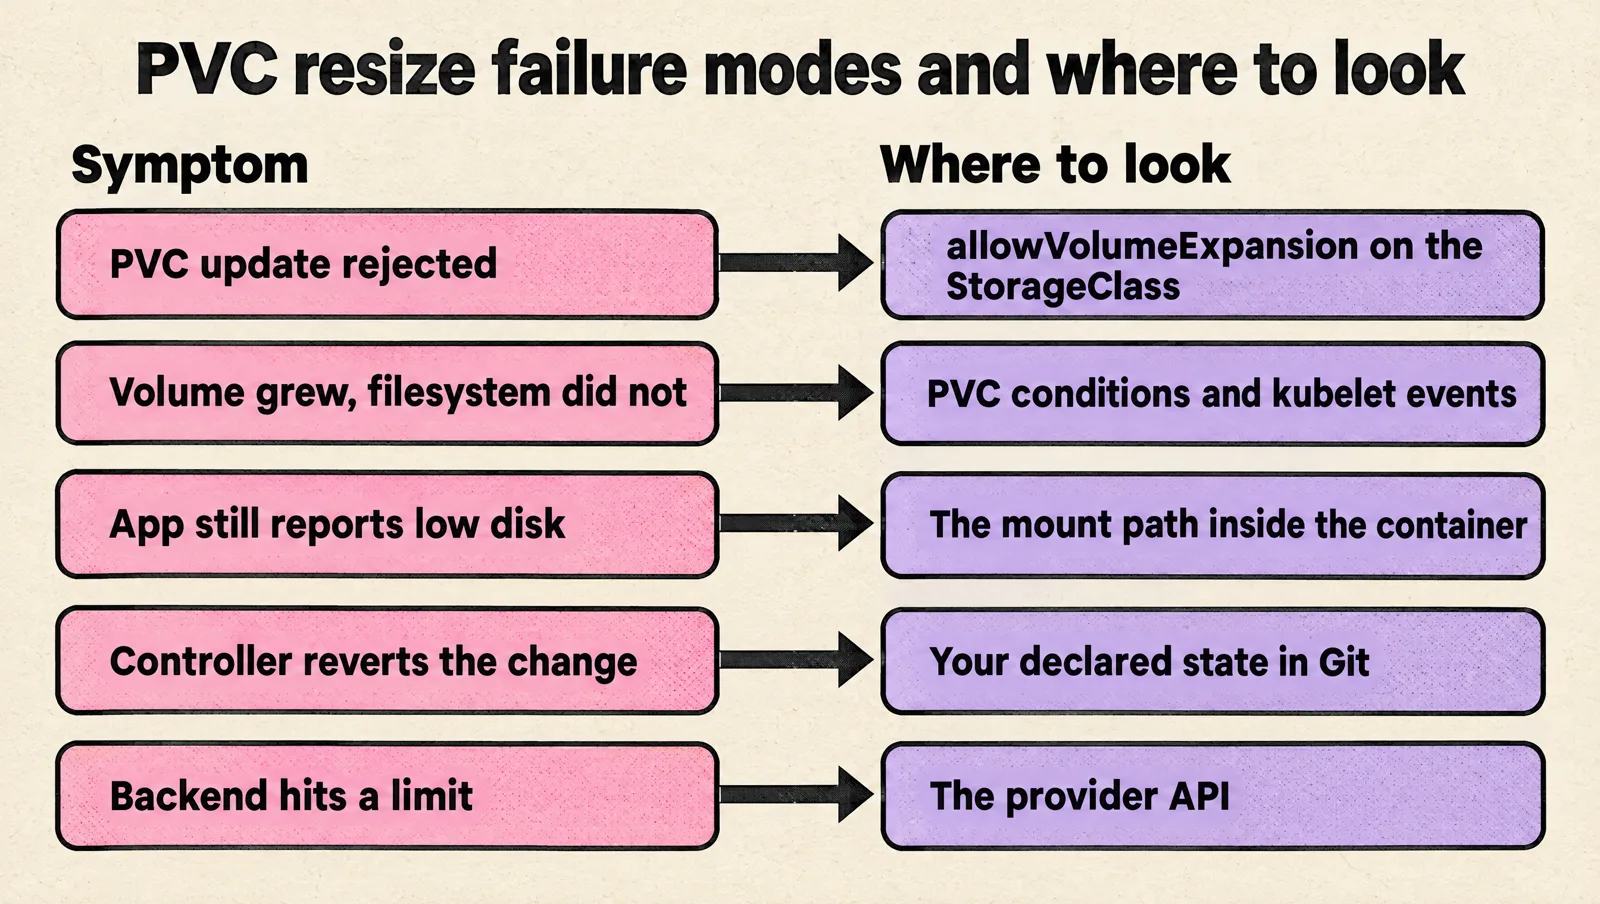
Most PVC expansions are uneventful when the storage stack supports them. The failures tend to come from assumptions, not from the patch command itself.
The StorageClass does not allow expansion
Kubernetes will reject the update if allowVolumeExpansion is missing or false. You can update the StorageClass for future attempts, but you should confirm that the underlying driver and storage backend support expansion before changing it.
The volume grows but the filesystem does not
If the PVC shows a larger capacity but the pod still sees the old filesystem size, check PVC conditions and kubelet events on the node. The filesystem resize may be pending until the pod restarts, especially with drivers that do not support online filesystem expansion.
The application still reports low disk space
Some applications cache disk checks or write to a different path than the mounted PVC. Confirm the mount path inside the container. For example, a pod may mount the PVC at /var/lib/postgresql/data, while an alert checks the container root filesystem.
A controller reverts or fights the change
Automation may re-apply old manifests. Even when Kubernetes does not shrink the volume, your configuration can become misleading. Update your declared state so future operators do not see conflicting values.
The storage backend hits a provider limit
Cloud disks, network file systems, and managed storage services have their own limits for maximum size, expansion frequency, performance tiers, and attachment behavior. Kubernetes will surface some errors in events, but the real cause may live in the provider API.
Managed platforms can reduce some operational burden, but they do not remove the need to understand the storage path. If you run workloads on Azure Kubernetes Service, Amazon Elastic Kubernetes Service, Google Kubernetes Engine, or self-managed clusters, the same basic checks still apply: StorageClass, CSI driver, filesystem, workload, and source of truth.
A safe operating pattern for production
For production systems, treat PVC expansion as a small change with a real runbook. You do not need a long maintenance window for every resize, but you do need a repeatable path.
A solid runbook looks like this:
- Open a change record or pull request. Include the target PVC, current size, new size, reason, and rollback constraints.
- Confirm backup status. PVC expansion is one-way at the Kubernetes level. If you choose the wrong size or expose a storage bug, restore may be your cleanest recovery path.
- Validate support in a lower environment. Use the same StorageClass and workload pattern where possible.
- Patch the PVC during a low-risk window. You may not need downtime, but you still want people available if the driver behaves differently than expected.
- Watch PVC events and pod logs. Do not stop at a successful
kubectl patch. - Verify inside the pod. Check the mounted filesystem and application health.
- Update desired state and documentation. Make the new size visible to the next person who touches the service.
This is the same mindset you need for other stateful platform work. In data-heavy systems, such as pipelines built with Apache Airflow, Kubernetes, cloud infrastructure, and Terraform, storage changes sit close to application reliability. A reference architecture for scalable biotech cloud infrastructure shows how orchestration, Kubernetes, and infrastructure code need to line up for dependable operations.
FAQ
Can I resize a PVC without restarting the pod?
Yes, if the CSI driver supports online expansion. Most current cloud drivers (AWS EBS, Google Persistent Disk, Azure Disk) do for ext4 and XFS. If the PVC shows the FileSystemResizePending condition and it does not clear, the driver needs the volume remounted, so restart the pod in a controlled way.
Can I shrink a PVC?
No. Kubernetes rejects a smaller storage request. To shrink, create a new, smaller PVC, copy the data (for example with a one-off Job running rsync or a database dump and restore), switch the workload over, then delete the old claim.
How do I resize the volumes of a StatefulSet?
Patch each PVC created from the template directly, then delete the StatefulSet with --cascade=orphan and re-apply it with the larger volumeClaimTemplates size. The steps are in the StatefulSet section above.
What does FileSystemResizePending mean?
The underlying volume has grown, but the filesystem on the node has not been expanded yet. With online expansion it clears on its own within a kubelet sync; with offline-only drivers it clears after the pod restarts.
Why is my PVC larger but df still shows the old size?
Usually the filesystem resize is still pending, or you are checking the wrong mount path. Run df -h on the PVC mount path inside the pod, and check kubectl describe pvc for conditions and events. The official reference is the Kubernetes docs on expanding persistent volume claims.
Takeaway
Resizing a Kubernetes PVC without downtime is realistic when the full path supports online expansion. Do the preflight checks, increase the PVC request, watch Kubernetes events, verify the filesystem from inside the pod, and update your source of truth. The command is small. The reliability comes from knowing which layer owns each part of the resize and checking the result before you move on.